Join discussions on data engineering best practices, architectures, and optimization strategies within the Databricks Community. Exchange insights and solutions with fellow data engineers.
HI Team,we have mounted our s3 buckets 2-3 years back and we don't have a place that has been maintained with config that are used to mount s3 bucket on data bricks instance. can we get complete config and keys/profiles that are used to mount s3 buck...
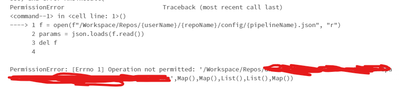
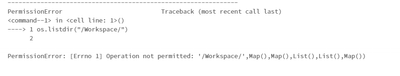
I had a working DLT pipeline that failed in the morning because it cannot read files from the Workspace or Repo directory. It is throwing an Operation not permitted error.Even when I am listing directories, it is throwing the same error (although it ...
currently I have some prblem about my DataBricks workspace when an user was deleted and it cause some issue:Applications or scripts that use the tokens generated by the user will no longer be able to access the Databricks APIJobs owned by the user wi...
I access databricks feature store outside databricks with databricks-connect on my IDE pycharm.The problem is just outside Databricks, not with a notebook inside Databricks.I use FeatureLookup mecanism to pull data from Feature store tables in my cus...
Also, Please refer to the below KB for additional resolution - https://learn.microsoft.com/en-us/azure/databricks/kb/dev-tools/dbconnect-protoserializer-stackoverflow
Consider a table that gets partitioned on a date field. But, I'm filtering a column that is not partitioned. Now, with this filter condition whether all the files are parsed to attain the required result set, or does any data skipping happens?
Hello. We would like to understand how many parquet files are created per data table. To be more specific, we refer to the current snapshot of the table. For example, we noticed that while we performed initial inserts to a table, one parquet file was...
I have a notebook (nb1) that calls another one (nb2) via the %run command. This returns some visualizations that I want to add to a dashboard of the caller notebook (nb1-db). When I select the visualization drop down, then select Add to dashboard, th...
Hi @Nicholas Couture , Could you please check and refer to https://docs.databricks.com/sql/user/security/access-control/dashboard-acl.html . Please let us know if this helps.
Hi, We are currently using a Azure AAD Token inorder to authenticate with Databricks instead of generating Personal Access Tokens from Databricks. We have a multi-tenant architecture and so we are using Azure container instances to run multiple trans...
Hello,
Please suggest how can we implement Referential Integrity (Primary Key / Foreign Key Constraint) - between different tables defined on Azure Databricks Database.
Basically the syntax to add Primary and Foreign Key constraint in the table defi...
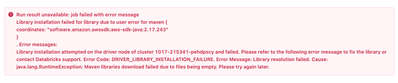
I have like 5 maven libraries, and with all of them, I have the same issue with Job or Notebooks. How much do I have to wait? is there another solution? Thank you very much!
Hi,there is no option to take VMs from a Pool for a new workflow (Azure Cloud)?default schema for a new cluster:{
"num_workers": 0,
"spark_version": "10.4.x-scala2.12",
"spark_conf": {
"spark.master": "local[*, 4]",
"spark...
Hi,
I tried following the Delta Live Tables quickstart (https://docs.databricks.com/data-engineering/delta-live-tables/delta-live-tables-quickstart.html), but I don't see the Pipelines tab under the Jobs page in my workspace.
The same guide mentions...
Hi, you need a Premium workspace for the Pipelines tab to show up. This is what I see on my workspace with Standard Pricing Tier selected: And this is what what I see on my workspace with the Premium Pricing Tier:
let us say I already have the data 'TotalData'write.csv(TotalData,file='/tmp/TotalData.csv',row.names = FALSE)I do not see any error from abovewhen I list files below:%fs ls /tmpI do not see any files written there. Why?
Hi Thiam,Thank you for reaching out to us. In this case it seems that you have written a file to the OS /tmp and tried to fetch the same folder in DBFS.Written >> /tmp/TotalData.csvReading >> /dbfs/tmp/TotalData.csvPlease try to execute write.csv wit...
Using Azure Databricks:I can create a DLT table in python usingimport dlt
import pyspark.sql.functions as fn
from pyspark.sql.types import StringType
@dlt.table(
name = "<<landingTable>>",
path = "<<storage path>>",
comment = "<< descri...