
- 1592 Views
- 1 replies
- 0 kudos
Databricks certificate exam got suspended, Need help to reschedule the exam
Hi @Cert-Team ,Today Mu Databricks certificate exam was suspended in the midway after approx 1 hour. Proctor asked me to show the room and after sometime he conveyed that my exam is being suspended and i will have to reach out to Databricks team for ...
- 1592 Views
- 1 replies
- 0 kudos
- 0 kudos
@Ajaykumar the support team has responded to your ticket.
- 0 kudos
- 3736 Views
- 6 replies
- 0 kudos
Getting an error while editing databrics metastore "databricks_metastore" using terraform (Azure)
Hi , I am getting an error (Metastore has reached the limit for metastores in region ) while updating metatsore using terraform , below the script i am using for updating metastore . There is already a metastore available i dont want to create the ne...
- 3736 Views
- 6 replies
- 0 kudos
- 0 kudos
Hi, Thank you for the suggestions, But i am still getting same error .
- 0 kudos
- 2406 Views
- 4 replies
- 0 kudos
Help to reschedule of my exam
Hi team,My Databricks Certified Data Engineer Associate exam got suspended within 40 minutes. I had also shown my exam room to the proctor. My exam got suspended due to watch. I was not using anything. Some questions are so big in the exam so I had t...
- 2406 Views
- 4 replies
- 0 kudos
- 3095 Views
- 1 replies
- 0 kudos
How to Resolve ConnectTimeoutError When Registering Models with MLflow
Hello everyone,I'm trying to register a model with MLflow in Databricks, but encountering an error with the following command: model_version = mlflow.register_model(f"runs:/{run_id}/random_forest_model", model_name) The error message is as follows:...
- 3095 Views
- 1 replies
- 0 kudos

- 0 kudos
@otara_geni if you are still struggling, try this - set the environmental variable in your code just before logging the model with the URL of the regional S3 endpoint (from the error it looks like MLFlow is attempting to use global one, which may not...
- 0 kudos
- 13435 Views
- 12 replies
- 2 kudos
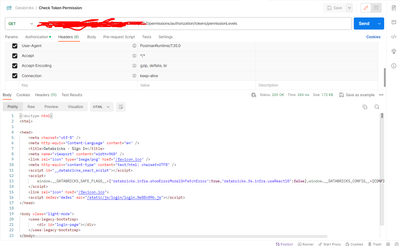
Getting HTML sign I page as api response from databricks api with statuscode 200
Response:<!doctype html><html><head> <meta charset="utf-8" /> <meta http-equiv="Content-Language" content="en" /> <title>Databricks - Sign In</title> <meta name="viewport" content="width=960" /> <link rel="icon" type="image/png" href="...
- 13435 Views
- 12 replies
- 2 kudos
- 2 kudos
Hey @schunduri, not entirely sure because our SRE did the change, but the machine the pipeline runs on must be within the same vnet as your DBKS workspace. If you need more guidance, I could try and check what we did but our SRE left the company sinc...
- 2 kudos
- 4361 Views
- 3 replies
- 0 kudos
What exactly is Vectorized query processing and columnar acceleration
Hey folks! I want to know and understand while using photon acceleration, there is a feature called columnar acceleration which basically is a method of storing data in columns rather than rows, which is particularly advantageous for analytical datab...
- 4361 Views
- 3 replies
- 0 kudos
- 0 kudos
Hi @szymon_dybczak, Thanks for reaching out! Please review the response and let us know if it answers your question. Your feedback is valuable to us and the community. If the response resolves your issue, kindly mark it as the accepted solution. This...
- 0 kudos
- 6265 Views
- 3 replies
- 1 kudos
How do I create spark.sql.session.SparkSession?
When I create a session n Databricks it is defaulting to spark.sql.connect.session.SparkSession. How can I connect to spark with out spark connect?
- 6265 Views
- 3 replies
- 1 kudos
- 1 kudos
Is there any solution to this? Pandera, Evidently and Ydata Profiling break because they don't speak a sql.connect session object. They expect a spark.sql.session.SparkSession it's very frustrating not being to use any of these libraries with the new...
- 1 kudos
- 4575 Views
- 2 replies
- 1 kudos
Structured Streaming from a delta table that is a dump of kafka and get the latest record per key
I'm trying to use Structured Streaming in scala to stream from a delta table that is a dump of a kafka topic where each record/message is an update of attributes for the key and no messages from kafka are dropped from the dump, but the value is flatt...
- 4575 Views
- 2 replies
- 1 kudos
- 1 kudos
I am confused about this recommendation. I thought the use of the append output mode in combination with aggregate queries is restricted to queries for which the aggregation is expressed using event-time and it defines a watermark.Could you clarify ?
- 1 kudos
- 5140 Views
- 3 replies
- 1 kudos
Resolved! Best Approach for Handling ETL Processes in Databricks
I am currently managing nearly 300 tables from a production database and considering moving the entire ETL process away from Azure Data Factory to Databricks.This process, which involves extraction, transformation, testing, and loading, is executed d...
- 5140 Views
- 3 replies
- 1 kudos

- 1 kudos
Hi,Instead of 300 individual files or one massive script, try grouping similar tables together. For example, you could have 10 scripts, each handling 30 tables. This way, you get the best of both approches—This way you will have a freedom of easy deb...
- 1 kudos
- 3426 Views
- 4 replies
- 3 kudos
Understanding Flight Cancellations and Rescheduling in Airlines Using Databricks and PySpark
In the airline industry, it’s important to manage flights efficiently. Knowing why flights get canceled or rescheduled helps improve customer satisfaction and operational performance. In this article, I’ll show you how to use Databricks and PySpark t...
- 3426 Views
- 4 replies
- 3 kudos

- 3 kudos
@Brahmareddy Interesting one , thanks for sharing
- 3 kudos
- 12127 Views
- 8 replies
- 0 kudos
Unable to reactive an inactive user
Hi all,I am facing an issue with reactivating an inactive user i tried the following json with databricks cli run_update = { "schemas": [ "urn:ietf:params:scim:api:messages:2.0:PatchOp" ], "Operations": [ { "op": "replace", "path": "ac...
- 12127 Views
- 8 replies
- 0 kudos

- 0 kudos
@FunkybunchOO Thank you for your response! I will look into other connections, but we are not currently using SCIM. There must be something similar blocking the activation.
- 0 kudos

- 989 Views
- 0 replies
- 0 kudos
UCX
Hey folks! I want to know what are the features that UCX does not provides in UC or specially Hive to UC Migration that can be done manually but not using UCX. As UCX is currently in developing mode so there are so many drawbacks, can someone share t...
- 989 Views
- 0 replies
- 0 kudos
- 777 Views
- 0 replies
- 0 kudos
databricks billing
Is there a way to use a business checking account to pay for Databricks services?
- 777 Views
- 0 replies
- 0 kudos

- 2313 Views
- 2 replies
- 0 kudos
Resolved! Translating XMLNAMESPACE in SQL Databricks
We are loading a data source that contains XML. I am translating their queries to create views in Databricks. They use 'XMLNAMESPACES' to construct/parse XML. Below is an example. What is best practice for translating 'XMLNAMESPACES' in Databricks?...
- 2313 Views
- 2 replies
- 0 kudos
- 0 kudos
Hi @TinaN, To handle XMLNAMESPACES in Databricks, use the from_xml function for parsing XML data, where you can define namespaces within your parsing logic. Start by reading the XML data using spark.read.format("xml"), then apply the from_xml functio...
- 0 kudos
- 1214 Views
- 1 replies
- 0 kudos
Can I load the files based on the data in my table as variable without iterating through each row?
Hi,I have created this table which contains the data that I need for my source path and target table. source_path: /data/customer/sid={sid}/abc=1/attr_provider={attr_prov}/source_data_provider_code={src_prov}/So basically, the value of each row are c...


- 1214 Views
- 1 replies
- 0 kudos
- 0 kudos
Hi @zll_0091, To efficiently load only the necessary files without manually iterating through each row of your table, you can use Spark's DataFrame operations. First, read your table into a DataFrame and determine the maximum key value. Then, filter ...
- 0 kudos
-
.CSV
1 -
Access Data
2 -
Access Databricks
3 -
Access Delta Tables
3 -
Account reset
1 -
adcAws databricks
1 -
ADF Pipeline
1 -
ADLS Gen2 With ABFSS
1 -
Advanced Data Engineering
2 -
AI
5 -
AIBI
1 -
Analytics
1 -
Apache spark
1 -
Apache Spark 3.0
1 -
api
1 -
Api Calls
2 -
API Documentation
4 -
App
2 -
Application
2 -
Architecture
1 -
asset bundle
1 -
Asset Bundles
3 -
Auto-loader
1 -
Autoloader
4 -
Aws databricks
1 -
AWS security token
1 -
AWSDatabricksCluster
1 -
Azure
7 -
Azure data disk
1 -
Azure Data Factory
1 -
Azure databricks
16 -
Azure Databricks Delta Table
1 -
Azure Databricks Job
1 -
Azure Databricks SQL
6 -
Azure databricks workspace
1 -
Azure Unity Catalog
6 -
Azure-databricks
1 -
AzureDatabricks
1 -
AzureDevopsRepo
1 -
best practices
1 -
Big Data Solutions
1 -
Billing
1 -
Billing and Cost Management
2 -
Blackduck
1 -
Bronze Layer
1 -
Business Intelligence
1 -
CDC
1 -
Certification
3 -
Certification Exam
1 -
Certification Voucher
3 -
Chrome
1 -
CICDForDatabricksWorkflows
1 -
Cloud_files_state
1 -
CloudFiles
1 -
Cluster
3 -
Cluster Init Script
1 -
Comments
1 -
Community Edition
4 -
Community Edition Account
1 -
Community Event
1 -
Community Group
2 -
Community Members
1 -
CommunityArticle
1 -
Compute
3 -
Compute Instances
1 -
conditional tasks
1 -
Connection
1 -
consulting
2 -
Contest
1 -
Course
1 -
Credentials
1 -
csv
1 -
Custom Python
1 -
CustomLibrary
1 -
DAIS2026
1 -
Dashboards
1 -
Data
1 -
Data + AI Summit
1 -
Data Engineer Associate
1 -
Data Engineering
4 -
Data Explorer
1 -
Data Governance
1 -
Data Ingestion
1 -
Data Ingestion & connectivity
1 -
Data Ingestion Architecture
1 -
Data Processing
1 -
Data Quality
1 -
Data Quality Checks
1 -
DataArchitecture
1 -
Databrick add-on for Splunk
1 -
databricks
6 -
Databricks Academy
1 -
Databricks AI + Data Summit
1 -
Databricks Alerts
1 -
Databricks App
2 -
Databricks Assistant
1 -
Databricks autoloader
1 -
Databricks Certification
1 -
Databricks Certified
1 -
Databricks champion
1 -
Databricks Cluster
2 -
Databricks Clusters
1 -
Databricks Community
11 -
Databricks community edition
3 -
Databricks Community Edition Account
1 -
Databricks Community Post
1 -
Databricks Community Rewards Store
3 -
Databricks connect
1 -
Databricks Dashboard
3 -
Databricks delta
2 -
Databricks Delta Table
2 -
Databricks Demo Center
1 -
Databricks Documentation
4 -
Databricks Error Message
1 -
Databricks genAI associate
1 -
Databricks JDBC Driver
2 -
Databricks Job
1 -
Databricks Lakeflow
2 -
Databricks Lakehouse Platform
6 -
Databricks Migration
1 -
Databricks Model
1 -
Databricks notebook
2 -
Databricks Notebooks
4 -
Databricks Partner
1 -
Databricks Platform
2 -
Databricks Pyspark
1 -
Databricks Python Notebook
1 -
Databricks Repo
1 -
Databricks Runtime
1 -
Databricks Serverless
2 -
Databricks SQL
5 -
Databricks SQL Alerts
1 -
Databricks SQL Visualizations
1 -
Databricks SQL Warehouse
1 -
Databricks Terraform
1 -
Databricks UI
1 -
Databricks Unity Catalog
5 -
Databricks User Group
1 -
Databricks Workflow
2 -
Databricks Workflows
2 -
Databricks workspace
3 -
Databricks-connect
1 -
databricks_cluster_policy
1 -
DatabricksJobCluster
1 -
DataCleanroom
1 -
DataDays
1 -
DataEngineering
1 -
DataGovernance
1 -
Datagrip
1 -
DataMasking
2 -
DataVersioning
1 -
dbdemos
2 -
DBFS
1 -
DBRuntime
1 -
DBSQL
1 -
DDL
1 -
Dear Community
1 -
deduplication
1 -
Delt Lake
1 -
Delta Live Pipeline
3 -
Delta Live Table
5 -
Delta Live Table Pipeline
5 -
Delta Live Table Pipelines
4 -
Delta Live Tables
7 -
Delta Sharing
2 -
Delta Time Travel
1 -
deltaSharing
1 -
Deny assignment
1 -
Development
1 -
DevOps
1 -
DLT
10 -
DLT Pipeline
7 -
DLT Pipelines
5 -
Dolly
1 -
Download files
1 -
DQX
2 -
Dynamic Variables
1 -
Engineering With Databricks
2 -
env
1 -
ETL Pipelines
1 -
Event Driven
1 -
External Sources
1 -
External Storage
2 -
FAQ for Databricks Learning Festival
2 -
Feature Store
2 -
File Trigger
1 -
Filenotfoundexception
1 -
Free Edition
1 -
Free trial
1 -
friendsofcommunity
1 -
GCP Databricks
1 -
GenAI
2 -
GenAI and LLMs
1 -
GenAI Course Material
1 -
Genie
2 -
Genie Agents
2 -
Getting started
3 -
Google Bigquery
1 -
Grafana
1 -
helpme
1 -
HIPAA
1 -
Hubert Dudek
2 -
IA
1 -
import
2 -
Integration
1 -
ISVPartnership
1 -
JDBC Connections
1 -
JDBC Connector
1 -
Job Task
1 -
JSON Object
1 -
Lake Flow Connect
1 -
Lakeflow Pipelines
1 -
LakeflowDesigner
1 -
Lakehouse
1 -
Learning
2 -
Lineage
1 -
link for labs
1 -
LLM
1 -
Login
1 -
Login Account
1 -
Login Issue
1 -
Machine Learning
3 -
MachineLearning
1 -
Market Place
1 -
MasterDataManagement
1 -
Materialized Tables
2 -
MDM
1 -
Medallion Architecture
1 -
meetup
2 -
Metadata
1 -
Migration
1 -
ML Model
2 -
MlFlow
2 -
Model
1 -
Model Serving
1 -
Model Training
1 -
Module
1 -
Monitoring
1 -
mosic ai search
1 -
Networking
2 -
Notebook
1 -
Onboarding
1 -
Onboarding Trainings
1 -
OpenAI
1 -
Optimization
1 -
Pandas udf
1 -
Permissions
1 -
personalcompute
1 -
Pipeline
2 -
Plotly
1 -
plugins
1 -
PostgresSQL
1 -
Pricing
1 -
provisioned throughput
1 -
Pyspark
1 -
Python
5 -
Python Code
1 -
Python Wheel
1 -
Quickstart
1 -
Read data
1 -
Repos Support
1 -
Reset
1 -
Rewards Store
2 -
Salesforce with Databricks
1 -
Sant
1 -
Schedule
1 -
Serverless
3 -
serving endpoint
1 -
Session
1 -
Sign Up Issues
2 -
Software Development
1 -
Spark
1 -
Spark Connect
1 -
Spark scala
1 -
sparkui
2 -
Speakers
1 -
Splunk
2 -
SQL
8 -
SQL Visualizations
1 -
streamlit
1 -
Summit23
7 -
Support Tickets
1 -
Sydney
2 -
Table Download
1 -
Tags
3 -
terraform
1 -
Training
2 -
Troubleshooting
1 -
Unity Catalog
4 -
Unity Catalog Metastore
2 -
UnityCatalog
1 -
Update
1 -
user groups
2 -
Venicold
3 -
Vnet
1 -
Voucher Not Recieved
1 -
VScode Extension
1 -
Watermark
1 -
Webinar
1 -
Weekly Documentation Update
1 -
Weekly Release Notes
2 -
Women
1 -
Workflow
2 -
Workspace
3
- « Previous
- Next »
| User | Count |
|---|---|
| 142 | |
| 123 | |
| 57 | |
| 46 | |
| 40 |


