
- 7166 Views
- 1 replies
- 1 kudos
Resolved! capture return value from databricks job to local machine by CLI
Hi,I want to run a python code on databricks notebook and return the value to my local machine. Here is the summary:I upload files to volumes on databricks. I generate a md5 for local file. Once the upload is finished, I create a python script with t...
- 7166 Views
- 1 replies
- 1 kudos

- 1 kudos
Hello @pshuk, You could check the below CLI commands: get-run-output Get the output for a single run. This is the REST API reference, which relates to the CLI command: https://docs.databricks.com/api/workspace/jobs/getrunoutput export-run There's al...
- 1 kudos
- 4295 Views
- 1 replies
- 0 kudos
Resolved! Error Code: METASTORE_DOES_NOT_EXIST when using Databricks API
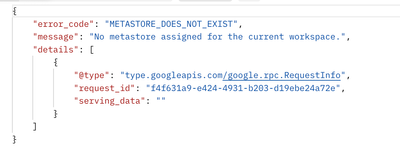
Hello, I'm attempting to use the databricks API to list the catalogs in the metastore. When I send the GET request to `/api/2.1/unity-catalog/catalogs` , I get this error I have checked multiple times and yes, we do have a metastore associated with t...
- 4295 Views
- 1 replies
- 0 kudos
- 0 kudos
Turns out I was using the wrong databricks host url when querying from postman. I was using my Azure instance instead of my AWS instance.
- 0 kudos
- 29003 Views
- 3 replies
- 5 kudos
Resolved! Use SQL Server Management Studio to Connect to DataBricks?
The Notebook UI doesn't always provide the best experience for running exploratory SQL queries. Is there a way for me to use SQL Server Management Studio (SSMS) to connect to DataBricks? See Also:https://learn.microsoft.com/en-us/answers/questions/74...
- 29003 Views
- 3 replies
- 5 kudos
- 5 kudos
What you can do is define a SQL endpoint as a linked server. Like that you can use SSMS and T-SQL.However, it has some drawbacks (no/bad query pushdown, no caching).Here is an excellent blog of Kyle Hale of databricks:Tutorial: Create a Databricks S...
- 5 kudos
- 4779 Views
- 1 replies
- 2 kudos
ingest csv file on-prem to delta table on databricks
Hi,So I want to create a delta live table using a csv file that I create locally (on-prem). A little background: So I have a working ELT pipeline that finds newly generated files (since the last upload), and upload them to databricks volume and at th...
- 4779 Views
- 1 replies
- 2 kudos
- 2 kudos
Hello @pshuk , Based on your description, you have an external pipeline that writes CSV files to a specific storage location and you wish to set up a DLT based on the output of this pipeline. DLT offers has access to a feature called Autoloader, whic...
- 2 kudos
- 3416 Views
- 3 replies
- 3 kudos
I am facing an issue while generating the DBU consumption report and need help.
I am trying to access the following system tables to generate a DBU consumption report, but I am not seeing this table in the system schema. Could you please help me how to access it?system.billing.inventory, system.billing.workspaces, system.billing...
- 3416 Views
- 3 replies
- 3 kudos
- 4252 Views
- 2 replies
- 0 kudos
Delta Sharing - Info about Share Recipient
What information do you know about a share recipient when they access a table shared to them via Delta Sharing?Wondering if we might be able to utilize something along the lines of is_member, is_account_group_member, session_user, etc for ROW and COL...
- 4252 Views
- 2 replies
- 0 kudos
- 0 kudos
Now that I'm looking closer at the share credentials and the recipient entity you would really need a way to know the bearer token and relate that back to various recipient properties - databricks.name and any custom recipient property tags you may h...
- 0 kudos
- 3639 Views
- 0 replies
- 0 kudos
Parallel kafka consumer in spark structured streaming
Hi,I have a spark streaming job which reads from kafka and process data and write to delta lake.Number of kafka partition: 100number of executor: 2 (4 core each)So we have 8 cores total which are reading from 100 partitions of a topic. I wanted to un...
- 3639 Views
- 0 replies
- 0 kudos
- 2480 Views
- 0 replies
- 1 kudos
how to develop Notebooks on vscode for git repos?
I am able to use vscode extension + databricks connect to develop Notebooks on my local computer and run them on my databricks cluster. However I can not figure out how to develop the Notebooks that have the file `.py` extension but identified by Dat...
- 2480 Views
- 0 replies
- 1 kudos
- 2251 Views
- 1 replies
- 0 kudos
Error While Running Table Schema
Hi All,I am facing issue while running a new table in bronze layer.Error - AnalysisException: org.apache.hadoop.hive.ql.metadata.HiveException: Unable to alter table.com.databricks.backend.common.rpc.SparkDriverExceptions$SQLExecutionException: org.a...
- 2251 Views
- 1 replies
- 0 kudos
- 0 kudos
Hello @Mirza1 , Could you please share the source code that is generating the exception, as well as the DBR version you are currently using? This will help me better understand the issue.
- 0 kudos
- 4894 Views
- 1 replies
- 0 kudos
Resolved! How does coalesce works internally
Hi Databricks team,I am trying to understand internals of spark coalesce code(DefaultPartitionCoalescer) and going through spark code for this. While I understood coalesce function but I am not sure about complete flow of code like where its get call...
- 4894 Views
- 1 replies
- 0 kudos
- 0 kudos
Hello @subham0611 , The coalesce operation triggered from user code can be initiated from either an RDD or a Dataset, with each having distinct codepaths: RDD: https://github.com/apache/spark/blob/master/core/src/main/scala/org/apache/spark/rdd/RDD...
- 0 kudos
- 11661 Views
- 2 replies
- 0 kudos
Resolved! Why saving pyspark df always converting string field to number?
import pandas as pd from pyspark.sql.types import StringType, IntegerType from pyspark.sql.functions import col save_path = os.path.join(base_path, stg_dir, "testCsvEncoding") d = [{"code": "00034321"}, {"code": "55964445226"}] df = pd.Data...
- 11661 Views
- 2 replies
- 0 kudos

- 0 kudos
@georgeyjy Try opening the CSV as text editor. I bet that Excel is automatically trying to detect the schema of CSV thus it thinks that it's an integer.
- 0 kudos
- 4432 Views
- 1 replies
- 0 kudos
Unable to access AWS S3 - Error : java.nio.file.AccessDeniedException
Reading file like this "Data = spark.sql("SELECT * FROM edge.inv.rm") Getting this error org.apache.spark.SparkException: Job aborted due to stage failure: Task 10 in stage 441.0 failed 4 times, most recent failure: Lost task 10.3 in stage 441.0 (TID...
- 4432 Views
- 1 replies
- 0 kudos
- 2062 Views
- 0 replies
- 0 kudos
Assessment(Assessment job need to be deployed using Terraform)
Assessment(Assessment job need to be deployed using Terraform)1.Install latest version of UCX 2.UCX will add the assessment job and queries to the workspace3.Run the assessment using ClusterHow to write code for this by using Terraform. Can anyone he...
- 2062 Views
- 0 replies
- 0 kudos
- 4374 Views
- 2 replies
- 0 kudos
Resolved! Unable to generate account level PAT for service principle
I am trying to generate PAT for a service principle.I am following the documentation as shown below:https://docs.databricks.com/en/dev-tools/auth/oauth-m2m.html#create-token-in-accountI have prepared the below curl command:I am getting below error:Pl...


- 4374 Views
- 2 replies
- 0 kudos
- 0 kudos
I was able to generate the workspace level token using the databricks cli.I set the following details in the databricks cli profile(.databrickscfg) file: host = https://myworksapce.azuredatabricks.net/ account_id = (my db account id)client_id = ...
- 0 kudos

- 10979 Views
- 2 replies
- 1 kudos
[Delta live table vs Workflow]
Hi Community Members,I have been using Databricks for a while, but I have only used Workflow. I have a question about the differences between Delta Live Table and Workflow. Which one should we use in which scenario?Thanks,
- 10979 Views
- 2 replies
- 1 kudos
- 1 kudos
Hi, Delta Live Tables focuses on managing data ingestion, transformation, and management of Delta tables using a declarative framework. Job Workflows are designed to orchestrate and schedule various data processing and analysis tasks, including SQL q...
- 1 kudos
-
.CSV
1 -
Access Data
2 -
Access Databricks
3 -
Access Delta Tables
3 -
Account reset
1 -
adcAws databricks
1 -
ADF Pipeline
1 -
ADLS Gen2 With ABFSS
1 -
Advanced Data Engineering
2 -
AI
5 -
AIBI
1 -
Analytics
1 -
Apache spark
1 -
Apache Spark 3.0
1 -
api
1 -
Api Calls
1 -
API Documentation
4 -
App
2 -
Application
2 -
Architecture
1 -
asset bundle
1 -
Asset Bundles
3 -
Auto-loader
1 -
Autoloader
4 -
Aws databricks
1 -
AWS security token
1 -
AWSDatabricksCluster
1 -
Azure
7 -
Azure data disk
1 -
Azure Data Factory
1 -
Azure databricks
16 -
Azure Databricks Delta Table
1 -
Azure Databricks Job
1 -
Azure Databricks SQL
6 -
Azure databricks workspace
1 -
Azure Unity Catalog
6 -
Azure-databricks
1 -
AzureDatabricks
1 -
AzureDevopsRepo
1 -
best practices
1 -
Big Data Solutions
1 -
Billing
1 -
Billing and Cost Management
2 -
Blackduck
1 -
Bronze Layer
1 -
Business Intelligence
1 -
CDC
1 -
Certification
3 -
Certification Exam
1 -
Certification Voucher
3 -
Chrome
1 -
CICDForDatabricksWorkflows
1 -
Cloud_files_state
1 -
CloudFiles
1 -
Cluster
3 -
Cluster Init Script
1 -
Comments
1 -
Community Edition
4 -
Community Edition Account
1 -
Community Event
1 -
Community Group
2 -
Community Members
1 -
CommunityArticle
1 -
Compute
3 -
Compute Instances
1 -
conditional tasks
1 -
Connection
1 -
consulting
2 -
Contest
1 -
Course
1 -
Credentials
1 -
csv
1 -
Custom Python
1 -
CustomLibrary
1 -
DAIS2026
1 -
Dashboards
1 -
Data
1 -
Data + AI Summit
1 -
Data Engineer Associate
1 -
Data Engineering
4 -
Data Explorer
1 -
Data Governance
1 -
Data Ingestion
1 -
Data Ingestion & connectivity
1 -
Data Ingestion Architecture
1 -
Data Processing
1 -
Data Quality
1 -
Data Quality Checks
1 -
DataArchitecture
1 -
Databrick add-on for Splunk
1 -
databricks
6 -
Databricks Academy
1 -
Databricks AI + Data Summit
1 -
Databricks Alerts
1 -
Databricks App
2 -
Databricks Assistant
1 -
Databricks autoloader
1 -
Databricks Certification
1 -
Databricks Certified
1 -
Databricks champion
1 -
Databricks Cluster
2 -
Databricks Clusters
1 -
Databricks Community
10 -
Databricks community edition
3 -
Databricks Community Edition Account
1 -
Databricks Community Rewards Store
3 -
Databricks connect
1 -
Databricks Dashboard
3 -
Databricks delta
2 -
Databricks Delta Table
2 -
Databricks Demo Center
1 -
Databricks Documentation
4 -
Databricks Error Message
1 -
Databricks genAI associate
1 -
Databricks JDBC Driver
2 -
Databricks Job
1 -
Databricks Lakeflow
2 -
Databricks Lakehouse Platform
6 -
Databricks Migration
1 -
Databricks Model
1 -
Databricks notebook
2 -
Databricks Notebooks
4 -
Databricks Partner
1 -
Databricks Platform
2 -
Databricks Pyspark
1 -
Databricks Python Notebook
1 -
Databricks Repo
1 -
Databricks Runtime
1 -
Databricks Serverless
2 -
Databricks SQL
5 -
Databricks SQL Alerts
1 -
Databricks SQL Visualizations
1 -
Databricks SQL Warehouse
1 -
Databricks Terraform
1 -
Databricks UI
1 -
Databricks Unity Catalog
4 -
Databricks User Group
1 -
Databricks Workflow
2 -
Databricks Workflows
2 -
Databricks workspace
3 -
Databricks-connect
1 -
databricks_cluster_policy
1 -
DatabricksJobCluster
1 -
DataCleanroom
1 -
DataDays
1 -
DataEngineering
1 -
DataGovernance
1 -
Datagrip
1 -
DataMasking
2 -
DataVersioning
1 -
dbdemos
2 -
DBFS
1 -
DBRuntime
1 -
DBSQL
1 -
DDL
1 -
Dear Community
1 -
deduplication
1 -
Delt Lake
1 -
Delta Live Pipeline
3 -
Delta Live Table
5 -
Delta Live Table Pipeline
5 -
Delta Live Table Pipelines
4 -
Delta Live Tables
7 -
Delta Sharing
2 -
Delta Time Travel
1 -
deltaSharing
1 -
Deny assignment
1 -
Development
1 -
DevOps
1 -
DLT
10 -
DLT Pipeline
7 -
DLT Pipelines
5 -
Dolly
1 -
Download files
1 -
DQX
2 -
Dynamic Variables
1 -
Engineering With Databricks
1 -
env
1 -
ETL Pipelines
1 -
Event Driven
1 -
External Sources
1 -
External Storage
2 -
FAQ for Databricks Learning Festival
2 -
Feature Store
2 -
File Trigger
1 -
Filenotfoundexception
1 -
Free Edition
1 -
Free trial
1 -
friendsofcommunity
1 -
GCP Databricks
1 -
GenAI
2 -
GenAI and LLMs
1 -
GenAI Course Material
1 -
Genie
1 -
Getting started
3 -
Google Bigquery
1 -
Grafana
1 -
helpme
1 -
HIPAA
1 -
Hubert Dudek
2 -
IA
1 -
import
2 -
Integration
1 -
ISVPartnership
1 -
JDBC Connections
1 -
JDBC Connector
1 -
Job Task
1 -
JSON Object
1 -
Lake Flow Connect
1 -
Lakeflow Pipelines
1 -
LakeflowDesigner
1 -
Lakehouse
1 -
Learning
2 -
Lineage
1 -
link for labs
1 -
LLM
1 -
Login
1 -
Login Account
1 -
Machine Learning
3 -
MachineLearning
1 -
Market Place
1 -
MasterDataManagement
1 -
Materialized Tables
2 -
MDM
1 -
Medallion Architecture
1 -
meetup
2 -
Metadata
1 -
Migration
1 -
ML Model
2 -
MlFlow
2 -
Model
1 -
Model Serving
1 -
Model Training
1 -
Module
1 -
Monitoring
1 -
mosic ai search
1 -
Networking
2 -
Notebook
1 -
Onboarding
1 -
Onboarding Trainings
1 -
OpenAI
1 -
Pandas udf
1 -
Permissions
1 -
personalcompute
1 -
Pipeline
2 -
Plotly
1 -
plugins
1 -
PostgresSQL
1 -
Pricing
1 -
provisioned throughput
1 -
Pyspark
1 -
Python
5 -
Python Code
1 -
Python Wheel
1 -
Quickstart
1 -
Read data
1 -
Repos Support
1 -
Reset
1 -
Rewards Store
2 -
Salesforce with Databricks
1 -
Sant
1 -
Schedule
1 -
Serverless
3 -
serving endpoint
1 -
Session
1 -
Sign Up Issues
2 -
Software Development
1 -
Spark
1 -
Spark Connect
1 -
Spark scala
1 -
sparkui
2 -
Speakers
1 -
Splunk
2 -
SQL
8 -
SQL Visualizations
1 -
streamlit
1 -
Summit23
7 -
Support Tickets
1 -
Sydney
2 -
Table Download
1 -
Tags
3 -
terraform
1 -
Training
2 -
Troubleshooting
1 -
Unity Catalog
4 -
Unity Catalog Metastore
2 -
UnityCatalog
1 -
Update
1 -
user groups
2 -
Venicold
3 -
Vnet
1 -
Voucher Not Recieved
1 -
VScode Extension
1 -
Watermark
1 -
Webinar
1 -
Weekly Documentation Update
1 -
Weekly Release Notes
2 -
Women
1 -
Workflow
2 -
Workspace
3
- « Previous
- Next »
| User | Count |
|---|---|
| 142 | |
| 123 | |
| 57 | |
| 46 | |
| 40 |


