
- 1754 Views
- 1 replies
- 0 kudos
GenAI democratizes AI field
Interesting to hear the latest tech trend at Data +AI summit.
- 1754 Views
- 1 replies
- 0 kudos

- 0 kudos
you can find the synthesis on a DAIS 2023 announcements here : https://medium.com/@youssefmrini/data-and-ai-summit-2023-announcements-6a4aade1d54c
- 0 kudos
- 7838 Views
- 3 replies
- 0 kudos
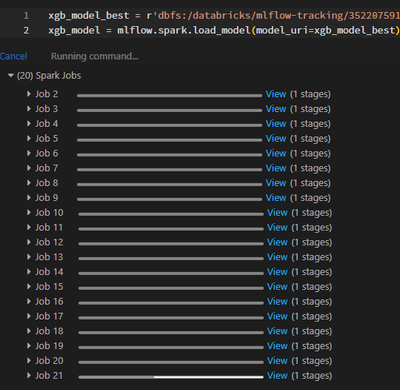
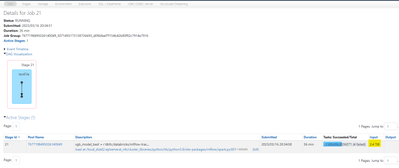
Resolved! Problems with xgboost.spark model loading from MLflow.
When loading an xgboost model from mlflow following the provided instructions in Databricks hosted MLflow the input sizes I am showing on the job are over 1 TB. Is anyone else using an xgboost.spark model and noticing the same behavior? Below are som...
- 7838 Views
- 3 replies
- 0 kudos
- 0 kudos
Thank you very much @Data_Cowboy !!! I had the same issue. I even had 14 TiB Databricks should really fix this
- 0 kudos
- 1762 Views
- 1 replies
- 0 kudos
Use OF API from package enerbitdso 0.1.8 PYPI
Hello! I have code to use an API supplied in the energitdso package (This is the repository https://pypi.org/project/enerbitdso/). I changed the code adapting it to AZURE DATABRICKS in python, but although there is a connection with the API, it does ...
- 1762 Views
- 1 replies
- 0 kudos
- 0 kudos
The owner of the package updated it to use the time out as a parameter of up to 20 seconds and updated a dependent package in DataBricks, with the above the problem was solved
- 0 kudos
- 3151 Views
- 1 replies
- 0 kudos
RBAC and VectorSearch
When implementing the managed VectorSearch, what is the preferred way to implement row based access control? I see that you can use the filter API during a query, so simple filters using a certain column may work, but what if all the security informa...
- 3151 Views
- 1 replies
- 0 kudos
- 0 kudos
Thanks AI for summarizing my question. However, you did not actually answer it.
- 0 kudos
- 2138 Views
- 0 replies
- 0 kudos
Optimal Cluster Configuration for Training on Billion-Row Datasets
Hello Databricks Community,I am currently facing a challenge in configuring a cluster for training machine learning models on a dataset consisting of approximately a billion rows and 40 features. Given the volume of data, I want to ensure that the cl...
- 2138 Views
- 0 replies
- 0 kudos
- 3941 Views
- 0 replies
- 0 kudos
Help - org.apache.spark.SparkException: Job aborted due to stage failure: Task 47 in stage 2842.0
Hello, I am training a SparkXGBRegressor model. It runs without errors if the complexity is low, however when I increase the max_depth and/or num_parallel_tree parameters, I get an error. I checked the cluster metrics during training and it doesn't l...
- 3941 Views
- 0 replies
- 0 kudos
- 7297 Views
- 2 replies
- 1 kudos
How to fix this runtime error in this Databricks distributed training tutorial workbook
I am following along with this notebook found from this article. I am attempting to fine tune the model with a single node and multiple GPUs, so I run everything up to the "Run Local Training" section, but from there I skip to "Run distributed traini...
- 7297 Views
- 2 replies
- 1 kudos
- 1 kudos
Hi AChang, have you eventually resolved the error? I've also having the same error.
- 1 kudos
- 3619 Views
- 2 replies
- 1 kudos
Resolved! import ml.dmlc.xgboost4j.scala.spark.{XGBoostEstimator, XGBoostClassificationModel}
how i can import : import com.microsoft.ml.spark.{LightGBMClassifier,LightGBMClassificationModel}import ml.dmlc.xgboost4j.scala.spark.{XGBoostEstimator, XGBoostClassificationModel} projet spark & scala in databricks
- 3619 Views
- 2 replies
- 1 kudos
- 1 kudos
XGBoostEstimator is not a member of package ml.dmlc.xgboost4j.scala.spark ?How can I resolve this error?with maven : ml.dmlc:xgboost4j-spark_2.12:2.0.3
- 1 kudos
- 1171 Views
- 0 replies
- 0 kudos
XGBoostEstimator is not a member of package ml.dmlc.xgboost4j.scala.spark ?
XGBoostEstimator is not a member of package ml.dmlc.xgboost4j.scala.spark ?How can I resolve this error?
- 1171 Views
- 0 replies
- 0 kudos
- 1508 Views
- 0 replies
- 0 kudos
Extract calculations naive bayes model
I have a naive Bayes ML model that takes call attributes and predicts if the caller is going to abandon the call while they are on hold waiting to speak to an agent. The model lives in Databricks ML flow, I have it registered. What I need to do is ex...
- 1508 Views
- 0 replies
- 0 kudos
- 2873 Views
- 2 replies
- 0 kudos
Unity Catalog table management with multiple teams members
Hi! How are you guys managing large teams working on the same project. Each member has their own data to save in Unity Catalog.Based on my understanding there is only two ways to manage this:1) Create an individual member schea so they can store thei...
- 2873 Views
- 2 replies
- 0 kudos
- 0 kudos
Any suggestions regarding this?@s_park , @Sujitha , @Debayan
- 0 kudos
- 1253 Views
- 0 replies
- 0 kudos
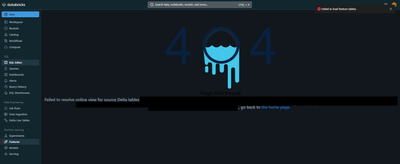
404 Page Not Found Error on Features page
We are facing this issue when accessing Features page. Our workspace is on AWS, ap-southeast-1.I think this is related to new feature for online tables and serverless. Is it because of online tables are not available yet in our region? If it not avai...
- 1253 Views
- 0 replies
- 0 kudos
- 6583 Views
- 5 replies
- 1 kudos
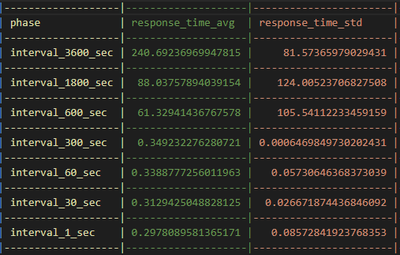
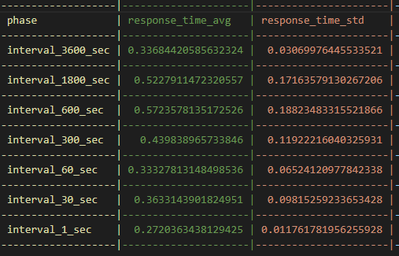
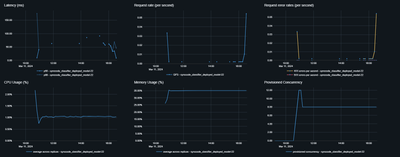
Resolved! Endpoint performance questions
Hi! Had really interesting results from some endpoint performance tests I did. I set up the non-optimized endpoint with zero-cluster scaling and optimized had this feature disabled.1) Why does the non-optimized endpoint have variable response time fo...
- 6583 Views
- 5 replies
- 1 kudos
- 1 kudos
Answering Q1: 1) The variable response time is due to the first endpoint response time requiring ~180 seconds to scale to 1 cluster from 02) Can i change zero scale time from the preset 30 min?
- 1 kudos
- 1922 Views
- 0 replies
- 0 kudos
Serving a custom transformer class via a pyfunc wrapper for a pyspark recommendation model
I am trying to serve an ALS pyspark model with a custom transformer(for generating user-specific recommendations) via a pyfunc wrapper. Although I can successfully score the logged model, the serving endpoint is throwing the following error.URI '/mod...
- 1922 Views
- 0 replies
- 0 kudos
- 49965 Views
- 25 replies
- 0 kudos
Problem when serving a langchain model on Databricks
I´m trying to model serving a LLM LangChain Model and every time it fails with this messsage:[6b6448zjll] [2024-02-06 14:09:55 +0000] [1146] [INFO] Booting worker with pid: 1146[6b6448zjll] An error occurred while loading the model. You haven't confi...
- 49965 Views
- 25 replies
- 0 kudos
- 0 kudos
Hi @DataWrangler and Team.I got to solve the initial problem from some tips you gave. I used your code as base and did some modifications adapted to what I have, I mean , No UC enabled and not able to use DatabricksEmbeddings, DatabricksVectorSearch ...
- 0 kudos
-
Access control
3 -
Access Data
2 -
AccessKeyVault
1 -
ADB
2 -
Airflow
1 -
Amazon
2 -
Apache
1 -
Apache spark
3 -
APILimit
1 -
Artifacts
1 -
Audit
1 -
Autoloader
6 -
Autologging
2 -
Automation
2 -
Automl
47 -
Aws databricks
1 -
AWSSagemaker
1 -
Azure
32 -
Azure active directory
1 -
Azure blob storage
2 -
Azure data lake
1 -
Azure Data Lake Storage
3 -
Azure data lake store
1 -
Azure databricks
32 -
Azure event hub
1 -
Azure key vault
1 -
Azure sql database
1 -
Azure Storage
2 -
Azure synapse
1 -
Azure Unity Catalog
1 -
Azure vm
1 -
AzureML
2 -
Bar
1 -
Beta
1 -
Better Way
1 -
BI Integrations
1 -
BI Tool
1 -
Billing and Cost Management
1 -
Blob
1 -
Blog
1 -
Blog Post
1 -
Broadcast variable
1 -
Business Intelligence
1 -
CatalogDDL
1 -
Centralized Model Registry
1 -
Certification
2 -
Certification Badge
1 -
Change
1 -
Change Logs
1 -
Check
2 -
Classification Model
1 -
Cloud Storage
1 -
Cluster
10 -
Cluster policy
1 -
Cluster Start
1 -
Cluster Termination
2 -
Clustering
1 -
ClusterMemory
1 -
CNN HOF
1 -
Column names
1 -
Community Edition
1 -
Community Edition Password
1 -
Community Members
1 -
Company Email
1 -
Condition
1 -
Config
1 -
Configure
3 -
Confluent Cloud
1 -
Container
2 -
ContainerServices
1 -
Control Plane
1 -
ControlPlane
1 -
Copy
1 -
Copy into
2 -
CosmosDB
1 -
Courses
2 -
Csv files
1 -
Dashboards
1 -
Data
8 -
Data Engineer Associate
1 -
Data Engineer Certification
1 -
Data Explorer
1 -
Data Ingestion
2 -
Data Ingestion & connectivity
11 -
Data Quality
1 -
Data Quality Checks
1 -
Data Science & Engineering
2 -
databricks
5 -
Databricks Academy
3 -
Databricks Account
1 -
Databricks AutoML
9 -
Databricks Cluster
3 -
Databricks Community
5 -
Databricks community edition
4 -
Databricks connect
1 -
Databricks dbfs
1 -
Databricks Feature Store
1 -
Databricks Job
1 -
Databricks Lakehouse
1 -
Databricks Mlflow
4 -
Databricks Model
2 -
Databricks notebook
10 -
Databricks ODBC
1 -
Databricks Platform
1 -
Databricks Pyspark
1 -
Databricks Python Notebook
1 -
Databricks Runtime
9 -
Databricks SQL
8 -
Databricks SQL Permission Problems
1 -
Databricks Terraform
1 -
Databricks Training
2 -
Databricks Unity Catalog
1 -
Databricks V2
1 -
Databricks version
1 -
Databricks Workflow
2 -
Databricks Workflows
1 -
Databricks workspace
2 -
Databricks-connect
1 -
DatabricksContainer
1 -
DatabricksML
6 -
Dataframe
3 -
DataSharing
1 -
Datatype
1 -
DataVersioning
1 -
Date Column
1 -
Dateadd
1 -
DB Notebook
1 -
DB Runtime
1 -
DBFS
5 -
DBFS Rest Api
1 -
Dbt
1 -
Dbu
1 -
DDL
1 -
DDP
1 -
Dear Community
1 -
DecisionTree
1 -
Deep learning
4 -
Default Location
1 -
Delete
1 -
Delt Lake
4 -
Delta lake table
1 -
Delta Live
1 -
Delta Live Tables
6 -
Delta log
1 -
Delta Sharing
3 -
Delta-lake
1 -
Deploy
1 -
DESC
1 -
Details
1 -
Dev
1 -
DevOps
1 -
Df
1 -
Different Notebook
1 -
Different Parameters
1 -
DimensionTables
1 -
Directory
3 -
Disable
1 -
Distribution
1 -
DLT
6 -
DLT Pipeline
3 -
Dolly
5 -
Dolly Demo
2 -
Download
2 -
EC2
1 -
Emr
2 -
Ensemble Models
1 -
Environment Variable
1 -
Epoch
1 -
Error handling
1 -
Error log
2 -
Eventhub
1 -
Example
1 -
Experiments
4 -
External Sources
1 -
Extract
1 -
Fact Tables
1 -
Failure
2 -
Feature Lookup
2 -
Feature Store
63 -
Feature Store API
2 -
Feature Store Table
1 -
Feature Table
6 -
Feature Tables
4 -
Features
2 -
FeatureStore
2 -
File Path
2 -
File Size
1 -
Fine Tune Spark Jobs
1 -
Forecasting
2 -
Forgot Password
2 -
Garbage Collection
1 -
Garbage Collection Optimization
1 -
Github
2 -
Github actions
2 -
Github Repo
2 -
Gitlab
1 -
GKE
1 -
Global Init Script
1 -
Global init scripts
4 -
Governance
1 -
Hi
1 -
Horovod
1 -
Html
1 -
Hyperopt
4 -
Hyperparameter Tuning
2 -
Iam
1 -
Image
3 -
Image Data
1 -
Inference Setup Error
1 -
INFORMATION
1 -
Input
1 -
Insert
1 -
Instance Profile
1 -
Int
2 -
Interactive cluster
1 -
Internal error
1 -
Invalid Type Code
1 -
IP
1 -
Ipython
1 -
Ipywidgets
1 -
JDBC Connections
1 -
Jira
1 -
Job
4 -
Job Parameters
1 -
Job Runs
1 -
Join
1 -
Jsonfile
1 -
Kafka consumer
1 -
Key Management
1 -
Kinesis
1 -
Lakehouse
1 -
Large Datasets
1 -
Latest Version
1 -
Learning
1 -
Limit
3 -
LLM
3 -
LLMs
4 -
Local computer
1 -
Local Machine
1 -
Log Model
2 -
Logging
1 -
Login
1 -
Logs
1 -
Long Time
2 -
Low Latency APIs
2 -
LTS ML
3 -
Machine
3 -
Machine Learning
24 -
Machine Learning Associate
1 -
Managed Table
1 -
Max Retries
1 -
Maximum Number
1 -
Medallion Architecture
1 -
Memory
3 -
Metadata
1 -
Metrics
3 -
Microsoft azure
1 -
ML Lifecycle
4 -
ML Model
4 -
ML Practioner
3 -
ML Runtime
1 -
MlFlow
75 -
MLflow API
5 -
MLflow Artifacts
2 -
MLflow Experiment
6 -
MLflow Experiments
3 -
Mlflow Model
10 -
Mlflow registry
3 -
Mlflow Run
1 -
Mlflow Server
5 -
MLFlow Tracking Server
3 -
MLModels
2 -
Model Deployment
4 -
Model Lifecycle
6 -
Model Loading
2 -
Model Monitoring
1 -
Model registry
5 -
Model Serving
35 -
Model Serving Cluster
2 -
Model Serving REST API
6 -
Model Training
2 -
Model Tuning
1 -
Models
8 -
Module
3 -
Modulenotfounderror
1 -
MongoDB
1 -
Mount Point
1 -
Mounts
1 -
Multi
1 -
Multiline
1 -
Multiple users
1 -
Nested
1 -
New Feature
1 -
New Features
1 -
New Workspace
1 -
Nlp
3 -
Note
1 -
Notebook
6 -
Notification
2 -
Object
3 -
Onboarding
1 -
Online Feature Store Table
1 -
OOM Error
1 -
Open Source MLflow
4 -
Optimization
2 -
Optimize Command
1 -
OSS
3 -
Overwatch
1 -
Overwrite
2 -
Packages
2 -
Pandas udf
4 -
Pandas_udf
1 -
Parallel
1 -
Parallel processing
1 -
Parallel Runs
1 -
Parallelism
1 -
Parameter
2 -
PARAMETER VALUE
2 -
Partner Academy
1 -
Pending State
2 -
Performance Tuning
1 -
Photon Engine
1 -
Pickle
1 -
Pickle Files
2 -
Pip
2 -
Points
1 -
Possible
1 -
Postgres
1 -
Pricing
2 -
Primary Key
1 -
Primary Key Constraint
1 -
Progress bar
2 -
Proven Practices
2 -
Public
2 -
Pymc3 Models
2 -
PyPI
1 -
Pyspark
6 -
Python
21 -
Python API
1 -
Python Code
1 -
Python Function
3 -
Python Libraries
1 -
Python Packages
1 -
Python Project
1 -
Pytorch
3 -
Reading-excel
2 -
Redis
2 -
Region
1 -
Remote RPC Client
1 -
RESTAPI
1 -
Result
1 -
Runtime update
1 -
Sagemaker
1 -
Salesforce
1 -
SAP
1 -
Scalability
1 -
Scalable Machine
2 -
Schema evolution
1 -
Script
1 -
Search
1 -
Security
2 -
Security Exception
1 -
Self Service Notebooks
1 -
Server
1 -
Serverless
1 -
Serving
1 -
Shap
2 -
Size
1 -
Sklearn
1 -
Slow
1 -
Small Scale Experimentation
1 -
Source Table
1 -
Spark config
1 -
Spark connector
1 -
Spark Error
1 -
Spark MLlib
2 -
Spark Pandas Api
1 -
Spark ui
1 -
Spark Version
2 -
Spark-submit
1 -
SparkML Models
2 -
Sparknlp
3 -
Spot
1 -
SQL
19 -
SQL Editor
1 -
SQL Queries
1 -
SQL Visualizations
1 -
Stage failure
2 -
Storage
3 -
Stream
2 -
Stream Data
1 -
Structtype
1 -
Structured streaming
2 -
Study Material
1 -
Summit23
2 -
Support
1 -
Support Team
1 -
Synapse
1 -
Synapse ML
1 -
Table
4 -
Table access control
1 -
Tableau
1 -
Task
1 -
Temporary View
1 -
Tensor flow
1 -
Test
1 -
Timeseries
1 -
Timestamps
1 -
TODAY
1 -
Training
6 -
Transaction Log
1 -
Trying
1 -
Tuning
2 -
UAT
1 -
Ui
1 -
Unexpected Error
1 -
Unity Catalog
12 -
Use Case
2 -
Use cases
1 -
Uuid
1 -
Validate ML Model
2 -
Values
1 -
Variable
1 -
Vector
1 -
Versioncontrol
1 -
Visualization
2 -
Web App Azure Databricks
1 -
Weekly Release Notes
2 -
Whl
1 -
Worker Nodes
1 -
Workflow
2 -
Workflow Jobs
1 -
Workspace
2 -
Write
1 -
Writing
1 -
Z-ordering
1 -
Zorder
1
- « Previous
- Next »
| User | Count |
|---|---|
| 90 | |
| 42 | |
| 38 | |
| 29 | |
| 25 |


