Dive into the world of machine learning on the Databricks platform. Explore discussions on algorithms, model training, deployment, and more. Connect with ML enthusiasts and experts.
https://docs.azure.cn/en-us/databricks/_static/notebooks/mlflow/mlflow-end-to-end-example-azure.htmlI imported the above notebook and try in Databricks community, but those subplots for Box plots are giving me errors as below:AttributeError ...
say, I want to download 2 files from this directory (dbfs:/databricks-datasets/abc-quality/") to my local filesystem, how do I do it?I understand that if those files are inside FileStore directory, it is much straightforward, which someone posts some...
Hi @THIAM HUAT TAN ,isn't this dbfs://databricks-datasets Databricks owned s3:// mounted to the workspace? You got an error - 403 access denied to PUT files into the s3 bucket: https://databricks-datasets-oregon.s3.us-west-2.amazonaws.com you shoul...
I am working through a basic example to get familiar with databricks automl. When I run classify, I hit an mlflow error. How can I avoid this error? My code:summary = databricks.automl.classify(train_df, target_col='new_cases', data_dir='dbfs:/automl...
Hi,When trying to create the first table in the Feature Store i get a message: ''DataFrame' object has no attribute 'isEmpty'... but it is not. So I cannot use the function: feature_store.create_table()With this code you should be able to reproduce t...
@Hubert DudekSry about the 'df_train', I forgot to change it (the error I commented is real with the proper DF). Changing the DBR to 11.3 LTS solved the problem. Thanks!
We're upgrading our ML jobs from using Runtime 9.1 LTS ML to Runtime 10.4 LTS ML in Databricks. One of the libraries our jobs relying on is Prophet. From 9.1 to 10.4, both the versions of Prophet (1.0.1) and PyStan (2.19.1.1) haven't changed, however...
We have a limit of deploying databricks shards and there are few shards that are unused. How can we check and remove these unlinked databricks shards using api calls
The help of `dbx sync` states that ```for the imports to work you need to update the Python path to include this target directory you're syncing to```This works quite well whenever the package is containing only driver-level functions. However, I ran...
Hi @Davide Cagnoni. Please see my answer to this post https://community.databricks.com/s/question/0D53f00001mUyh2CAC/limitations-with-udfs-wrapping-modules-imported-via-repos-filesI will copy it here for you:If your notebook is in the same Repo as t...
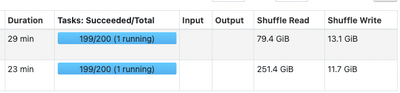
I have a dataset about 5 million rows with 14 features and a binary target. I decided to train a pyspark random forest classifier on Databricks. The CPU cluster I created contains 2 c4.8xlarge workers (60GB, 36core) and 1 r4.xlarge (31GB, 4core) driv...
I'm running databricks version 10.4 on gcp. I'm running a structured stream trying to process historical files in a delta table on gcp cloud storage. This source delta table is big but maintained with OPTIMIZE.The stream repartitions which seems to b...
Hi @Dwight Branscombe Hope all is well! Just wanted to check in if you were able to resolve your issue and would you be happy to share the solution or mark an answer as best? Else please let us know if you need more help. We'd love to hear from you....
I am planning to deploy MLFlow server deployed in Azure as a centralised repositories for my machine learning experiments and runs and to store events and artifacts. I would like to have different environments or isolated environments in the same wor...
Hi @Hemanth Vakacharla Does @Debayan Mukherjee response answer your question? If yes, would you be happy to mark it as best so that other members can find the solution more quickly?We'd love to hear from you.Thanks!
Hello guys,I'm using Jira API to return "ISSUES". But to be able to use pyspark I need to create the Dataframe passing in the Schema. But I am not able to create the Schema based on the model below. Would you have any ideas?root
|-- expand: string ...
if columns are missing, that particular data is not present in the json. I am not aware of spark skipping columns when reading json with inferschema. There is an option dropFieldIfAllNull but that is False by default.That makes me think: you might ...
I like to train my machine learning model from Pycharm IDE. But I want to utilize databricks cluster as compute power to speed up the training. Is it possible
Hi @Suvikram Yerramilli Hope all is well! Just wanted to check in if you were able to resolve your issue and would you be happy to share the solution or mark an answer as best? Else please let us know if you need more help. We'd love to hear from yo...
Hello, I have a question about best practice regarding registering a feature in Databricks feature store.Lets say that I create and register features during the EDA or experiment phase of a ML project. Later the model is moving to production stage ...
Hi @Willis Harding Does @Kaniz Fatma response answer your question? If yes, would you be happy to mark it as best so that other members can find the solution more quickly?We'd love to hear from you.Thanks!
Hello, I need assistance accessing my account in data bricks community edition. I got an error that my account was locked due to recent suspicious activity. I tried to reset my password but did not get an email with password change instructions. Than...