passing array as a parameter to PandasUDF
- Mark as New
- Bookmark
- Subscribe
- Mute
- Subscribe to RSS Feed
- Permalink
- Report Inappropriate Content
08-04-2022 12:22 PM
Hi Team,
My python dataframe is as below.
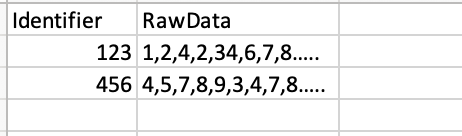
Python Function
def calculate_metrics(value_dict):
df = value_dict.copy()
df['Metric1'] =pd.Series(dtype='float')
df['Metric2'] = pd.Series(dtype='float')
for index,row in value_dict.iterrows():
df.loc[df['Id']==row['Id'],'Metric1'] = Function1(row['RawData'])
df.loc[df['Id']==row['Id'],'Metric2'] = Function2(row['RawData'])
return df
Here I pass a data frame value_dict with "Identifier and RawData" as two columns.
I call as below
value_dict['RawData'] = value_dict['RawData'].apply(lambda x: np.array(x))
df_Fullagg = calculate_metrics(value_dict)
This calculates all the metrics I need and returns in a dataframe.
The volumen of data is quite high here. I want to use spark frame work here with azure synapse. How can I write the same function using pandas_Udf.
I am looking for some implementation like this.
@pandas_udf('int', PandasUDFType.SCALAR)
def calculate_metrics(value_dict):
df = value_dict.copy()
df['Metric1'] =pd.Series(dtype='float')
df['Metric2'] = pd.Series(dtype='float')
for index,row in value_dict.iterrows():
df.loc[df['Id']==row['Id'],'Metric1'] = Function1(row['RawData'])
df.loc[df['Id']==row['Id'],'Metric2'] = Function2(row['RawData'])
return df
Any help would be much appreciated.
- Labels:
-
Array
-
Parameter
-
Python
-
Python Dataframe
- Mark as New
- Bookmark
- Subscribe
- Mute
- Subscribe to RSS Feed
- Permalink
- Report Inappropriate Content
08-07-2022 07:45 AM
Hi, it seems you do not need a pandas udf here. Try the following :
import numpy as np
from pyspark.sql.types import FloatType
from pyspark.sql import functions as f

data = [{"Identifier": 123, "RawData": "1,2,4,2,34,6,7,8"},
        {"Identifier": 456, "RawData": "4,5,7,8,9,3,4,7,8"}]

df = spark.createDataFrame(data)

series_mean = f.udf(lambda x: float(np.mean(x)), FloatType()) # replace by Metric1 logic
series_max = f.udf(lambda x: float(np.max(x)), FloatType()) # replace by Metric2 logic

df = (df
      .withColumn("series_int", f.split(f.col('RawData'), ',').cast('array<int>'))
      .withColumn("mean", series_mean("series_int"))
      .withColumn("max", series_max("series_int"))
     )

display(df)
- Mark as New
- Bookmark
- Subscribe
- Mute
- Subscribe to RSS Feed
- Permalink
- Report Inappropriate Content
09-07-2022 04:36 AM
Hello @Kausthub NP
Hope all is well! Just wanted to check in if you were able to resolve your issue and would you be happy to share the solution or mark an answer as best? Else please let us know if you need more help.
We'd love to hear from you.
Thanks!

