Dive into a collaborative space where members like YOU can exchange knowledge, tips, and best practices. Join the conversation today and unlock a wealth of collective wisdom to enhance your experience and drive success.
This is super amazing and super powerful -https://docs.databricks.com/aws/en/generative-ai/mcp/managed-mcpEssentially we you can use Databricks managed MCP servers to seamlessly integrate Databricks features into any AI Agent. That's the multiplier ...
If you’ve ever hacked together a one-off script to pull data from some random API into Spark, you’re exactly who the new Python Data Source API is for.
Databricks has made this API generally available on Apache Spark™ 4.0 with Databricks Runtime 1...
I have seen multiple glue jobs pulling data from such systems. This is certainly a solution to simplify and bring governance to it. will look forward to implement it.#Apache-4
You spend hours sizing clusters, tuning autoscaling configurations, and optimizing instance types.Clusters sit idle burning money between jobs or take minutes to start when you need them immediately.Managing compute infrastructure becomes a full-time...
Last night I delivered my final session on Databricks + Power BI integration and it felt like the right moment to close this chapter on a high note. Because it was the last time I was presenting this topic, I rebuilt the flow completely. Instead of ...
Yesterday in Chicago, I attended one of the final stops of the Databricks DAIWT (Data & AI World Tour).
This tour brings the excitement and passion of our annual Data + AI Summit to over a dozen cities worldwide, in a condensed format.
Packed into ...
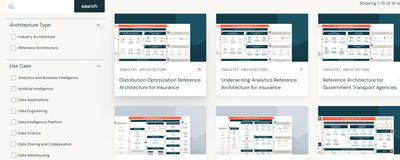
Databricks Architecture Center — Your Blueprint for Building Modern Data & AI PlatformsThe Databricks Architecture Center is a centralized knowledge hub that provides:End-to-end reference architecturesIndustry-specific patternsArchitecture decision ...
Hey everyone I’m excited to share the progress of my Databricks learning journey! Recently, I worked on building an end-to-end ETL pipeline in Databricks, starting from data extraction from AWS S3 to creating a dynamic dashboard for insights.Here’s h...
@Rohan_Samariya this is fantastic work! I’m genuinely impressed with how you’ve taken the Databricks stack end-to-end: S3 ingestion → PySpark transformations → Delta optimisation → interactive SQL dashboards. This is exactly the type of hands-on, fu...
I launched a new app this week to help keep track of Databricks releases.you can view and filter the latest releases in the timeline view, or go to the resources page and go to a product area and see the latest releases alongside useful links for blo...
Tips and Techniques for Ingesting Large JSON files with PySparkIntroductionSuppose you’ve ever struggled or grappled with consuming massive JSON files with PySpark. In that case, you are aware that insufficient data can always creep in and silently d...
Hi everyone, For the Databricks Free Edition Hackathon, I wanted to show that traditional ML still has a big role today, and how it can work hand-in-hand with Databricks’ newer AI tooling. As a concrete use case, I created a recipe recommendation eng...
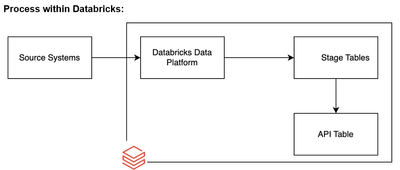
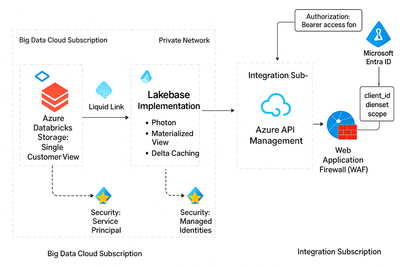
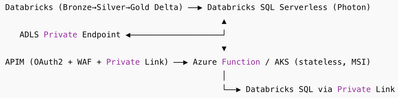
In this blog, I will be talking about the building the architecture to serve the API consumption on Databricks Platform. I will be using Lakebase approach for this. It will be useful for this kind of API requirement.API Requirement: Performance:Curre...
Hey everyone I recently started my Databricks learning journey about a month ago, and I wanted to share what I’ve learned so far from one beginner to another.Here are a few highlights:1️⃣ Understanding the Lakehouse Concept - Realized how Databricks ...
I was planning to build an ETL pipeline, but I hadn’t considered using MLflow to predict sales and ratings. Thanks for the suggestion, I’ll work on creating this demo soon to test and enhance my skills.
Hi All, How are you doing today?I wanted to share something interesting from my recent Databricks work — I’ve been playing around with an idea I call “Real-Time Metadata Intelligence.” Most of us focus on optimizing data pipelines, query performance,...
I like the core idea. You are mining signals the platform already emits.I would start rules first, track small files ratio and average file size trend, watch skew per partition and shuffle bytes per input gigabyte. Compare job time to input size to c...
Join us tomorrow, Thursday, Nov 13 at 9 am PT for the latest BrickTalks! We'll talk about bringing data intelligence from your Lakehouse into every app. Register now.
What you’ll learn:
Use Lakebase (PostgreSQL-compatible, serverless OLTP) to serve...
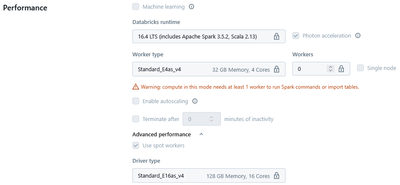
Wanted to share something that might save others time and money. We had a complex Databricks script that ran over 1.5 hours, when the target was under 20 minutes. Initially tried scaling up the cluster, but real progress came from simply upgrading th...