
Databricks Platform Discussions
Dive into comprehensive discussions covering various aspects of the Databricks platform. Join the co...
17008 Posts
Dive into comprehensive discussions covering various aspects of the Databricks platform. Join the co...
Engage in vibrant discussions covering diverse learning topics within the Databricks Community. Expl...
Hi,I'm experiencing an issue with a Databricks notebook after restarting a cluster that has a custom library installed.Here are the steps I followed:Created a Databricks compute cluster.Attached a notebook to the cluster.Installed a library required ...

Hello @DineshOjha, Short answer: this isn't expected behavior. When terminated compute starts again, Databricks recreates it, reinstalls the configured libraries, and reattaches notebooks. If a library is still pending, fails to install, or conflict...
We are using AUTO CDC (APPLY CHANGES INTO) to process change data capture events from an upstream source (via Autoloader ingesting CDC files landed in cloud storage) into our Silver layer tables. Our source occasionally delivers out-of-order events —...
Hello @Khasim_1, I took a look at both internal and external documentation and here is what I found. You're in good hands in this thread already. @Brahmareddy's STRUCT suggestion and @data_pulse's test both line up with the documented behavior, and @...
Hi!I create a bundle with databricks bundle initand i let create a pipeline including a package. The pipeline definition looks like the following# The main pipeline for pipelinewithpackage resources: pipelines: pipelinewithpackage_etl: n...

Hello @a_user12, . Your bundle config is the documented pattern for pulling pyproject.toml dependencies into a pipeline, so the setup itself is sound. The clue is the 1,433-byte wheel. An editable install doesn't copy your code into site-packages. It...
I have a data ingestion pipeline ingesting ServiceNow data into databricks. It has been working for several months, but it stopped working since October 1st.From what I see, the pipeline suffered connection time out.However, from the connection, I ca...

Hello @skao, I took a look at both internal and external documentation and here is what I found. A working token refresh and an active ServiceNow account are good signs, but they don't rule out a connectivity or ServiceNow API performance problem. Ge...

Is see that kafka for zerobus is still in beta. So maybe something will change. Can someone tell me whether they are aware of an authentication handshake with this API that might AVOID the callback?Here is the python example, which uses a sophistica...
Glad I could be a help. Cheers, Lou.
Hi,We have recently been evaluating TellR and are very interested in the concept of generating presentation-ready management decks directly from governed data through conversational interactions.From our perspective, the ability to transform insights...
<a href="https://www.peptidesourcelap.com/product/nad-750mg-for-sale/">nad 750mg for sale</a><a href="https://www.peptidesourcelap.com/product/nad-100mg-for-sale/">nad 100mg for sale</a>
Hello dear community, i am trying to revoke permissions with the API for SQL-Warehouse. Granting permissions isn't a problem and works like a charme. But revoking won't function. I tried "NO_PERMISSIONS", "NO PERMISSIONS", "DENY", "REVOKE" But i al...
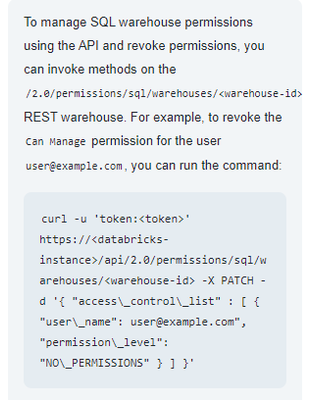
Have you tried checking the latest Databricks API documentation for the correct permission values and how to remove existing access? It would be helpful if someone could share a working example, since granting permissions seems to work but revoking t...
I’m noticing some unusual inconsistencies in how scripts execute on databricks.com compared to when the same workflow is triggered through a mobile-based API. On Databricks, the script runs perfectly when executed directly inside a cluster notebook. ...
I’d start by checking environment variables, session initialization, and cluster startup differences between notebook runs and API-triggered executions. Logging timestamps and outputs at each step could help identify where the behavior changes. It wo...
looking for free certification voucher
I have completed both Associate Data Engineering and Professional Data Engineering Learning Path and also got the credential badges as well. Looking forward to receiving the voucher after the festival is finished.
I'm learning Databricks, and I'm interested in using it to analyze data from a gaming website focused on Tomodachi Life ROM .I'd like to understand the best approach for building a simple analytics workflow.Some questions I have are:How can I import ...
Databricks is a good option for learning website analytics because you can combine data preparation, SQL queries, PySpark, and visualizations in one workflow. I’d start by importing a CSV export from Google Analytics 4, checking for missing values, a...
hello everyone, I'm trying use spotify's api to analyse my music data, but i'm receiving a error during authentication, specifically when I try get the token, above my code.Is it a databricks bug?pip install spotipyfrom spotipy.oauth2 import SpotifyO...
This error usually occurs because SpotifyOAuth is trying to request interactive input, which Databricks notebooks may not support. You can resolve it by configuring the Spotify authorization flow correctly, including the redirect URI, and obtaining t...
Super excited about learning how AI can help improve performance and throughout for our database customers.
Interesting topic! Could you explain how indexless indexes work and how they can improve database query performance? I’d be interested to learn about their practical use cases and any limitations compared with traditional indexing.

Hi AllI am having situation where I wanted to run job as continuous trigger by using job cluster, cluster terminating and re-creating in every run within continuous trigger.I just wanted two know if we have any option where I can use same job cluster...

Managing job clusters with continuous triggers can be challenging, especially when a cluster terminates and must be recreated for every run. Reusing the same cluster could potentially reduce startup delays and improve resource efficiency, depending o...
Hi everyone,I'm currently preparing for the Databricks Certified Data Engineer Associate exam and have started the Data Engineer Learning Plan on Databricks Academy (11 e-learning courses, about 16 hours in total). It covers topics like:Data Ingestio...
Adding to Vlad's answer, here are a few areas from the current exam guide (May 2026) that are easy to under-prepare from the courses alone:Governance and Security (15%): practise Unity Catalog access control with GRANT, REVOKE and DENY, managed vs ex...
Following up on the trust-tier mechanics iyashk-DB explained in this thread (https://community.databricks.com/t5/generative-ai/foundation-models-api-blocked-quot-databricks-set-rate-limit-of/m-p/160952) and this one (https://community.databricks.com/...

Short answer: I'm not aware of any self-service action, in the workspace or the account console, that promotes an account's trust tier. That's a Databricks-side determination, so someone at Databricks has to act on it. The Anthropic 401 is a separat...
| User | Count |
|---|---|
| 1900 | |
| 1047 | |
| 931 | |
| 480 | |
| 390 |


