

- 2056 Views
- 5 replies
- 12 kudos
Resolved! LLM based Replies to community posts
Hello Everyone,I’ve been in the community for a few weeks and really enjoy reading the problems and production-focused solutions shared here.Recently, I’ve noticed some replies(solutions) that look quite verbose and seem like they might be generated ...
- 2056 Views
- 5 replies
- 12 kudos

- 12 kudos
Hey guys, I appreciate you bringing this up. We do have an AI usage policy in our Code of Conduct that I recently asked Legal to update:Use of AI Tools: AI tools may be used to assist with formatting, clarity, and organization, or to draft ideas that...
- 12 kudos
- 1042 Views
- 4 replies
- 0 kudos
Attempting to load a JSON file fails due to schema issue (Free Edition)
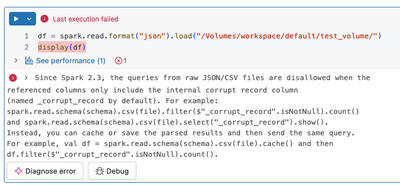
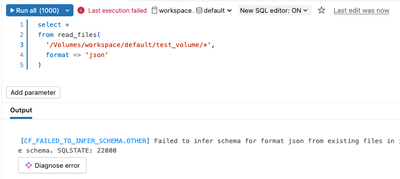
Hello,I created a Volume named 'test_volume' under catalog:workspace and schema:default.Then I uploaded a file named user_0.json into test_volume (fake data, of course):Now I want to load that file into a data frame.With Python in a notebook:With SQL...

- 1042 Views
- 4 replies
- 0 kudos

- 0 kudos
The AnalysisException you're seeing in the Databricks Community Edition is almost always caused by a mismatch between the JSON file format and Spark’s default reader.By default, Spark expects JSON Lines (one JSON object per line). If your file is a s...
- 0 kudos
- 3593 Views
- 5 replies
- 3 kudos
Resolved! “Provisioned throughput is not enabled for this workspace”
Hello,when I try setting up a model with provisioned throughput, the deployment fails with the message “Provisioned throughput is not enabled for this workspace.”. It doesn’t work for databricks-hosted models nor for 3rd party models from the marketp...

- 3593 Views
- 5 replies
- 3 kudos
- 3 kudos
Hello Steve,thank you for the broad reply. Just FYI I had to reach to to Azure support and DB support to fix it.FYI 2: Serverless compute was enabled, `Enforce data processing within workspace Geography for Designated Services was disabled`, pay-per-...
- 3 kudos
- 1812 Views
- 2 replies
- 0 kudos
Resolved! How to auto‑terminate DLT-managed clusters after pipeline execution?
We have Data bricks Jobs that run a combination of DLT pipelines and notebook tasks.For the notebook tasks, we use a job cluster, and we are able to auto‑terminate it after execution using auto termination: 10However, the DLT-managed clusters behave ...
- 1812 Views
- 2 replies
- 0 kudos

- 0 kudos
Hi @anusha98, The behavior you are seeing, where the cluster stays running for a long time after pipeline completion, is almost certainly because your pipeline is running in Development mode. In Development mode, the default cluster shutdown delay is...
- 0 kudos
- 875 Views
- 2 replies
- 1 kudos
Manager hierarchy
for employee manager hierarchy some employees are not having correct manager mapping, what can be the reason?
- 875 Views
- 2 replies
- 1 kudos
- 1 kudos
Hi @spjti, Incorrect manager mappings in an employee hierarchy typically come from a few common root causes. Since the question is fairly open-ended, here is a checklist of the most likely issues and how to diagnose them in Databricks. COMMON REASONS...
- 1 kudos
- 1947 Views
- 6 replies
- 0 kudos
Same Delta Table, Different Behavior: Dev vs Prod Workspace in Databricks
I recently ran into an interesting Databricks behavior while implementing a row-count comparison using Delta Time Travel (VERSION AS OF).Platform: AzureScenario:Same Unity CatalogSame fully qualified tableSame table ID, location, and Delta formatYet ...
- 1947 Views
- 6 replies
- 0 kudos
- 0 kudos
Hi @Smriti2, The error "TIME TRAVEL is not allowed. Operation not supported on Streaming Tables" when the table is not intentionally a streaming table typically points to the table having pipeline-related metadata attached to it in the prod workspace...
- 0 kudos
- 2426 Views
- 4 replies
- 0 kudos
Databricks Dataframe: Merge exception for string column in delta table with change detectio enabled.
Hi,I am trying to append change data records into delta table using dataframe. However, I am encountering an issue while appending new records to existing data in delta table. The exception raised isCannot merge columns 'ColumnX' into 'ColumnX'Both n...
- 2426 Views
- 4 replies
- 0 kudos
- 0 kudos
Hi @crami, The "Cannot merge columns 'ColumnX' into 'ColumnX'" error you are seeing is caused by passing "delta.enableChangeDataFeed" as a write option on the DataFrame writer. Change Data Feed (CDF) is a table-level property, not a per-write option....
- 0 kudos

- 1525 Views
- 1 replies
- 0 kudos
Inconsistent UNRESOLVED_COLUMN._metadata error on Serverless compute during MERGE operations
Hi.I've been facing this problem for the last couple of days.We're experiencing intermittent failures with the error [UNRESOLVED_COLUMN.WITHOUT_SUGGESTION] A column, variable, or function parameter with name '_metadata' cannot be resolved. SQLSTATE: ...
- 1525 Views
- 1 replies
- 0 kudos
- 0 kudos
Hi @ruicarvalho_de, The behavior you are seeing is related to how the _metadata virtual column interacts with Spark Connect (which Serverless compute uses under the hood) and how deferred analysis changes when that hidden column is resolved. Here is ...
- 0 kudos
- 2892 Views
- 5 replies
- 0 kudos
databricks list job runs api limit doesnt work
noticed that the limit parameter on the list job runs api: https://docs.databricks.com/api/workspace/jobs/listrunsdoesnt work. no matter what limit i set, i always get all the runs which can be too many if i want all runs.If i set offset as > 1, then...
- 2892 Views
- 5 replies
- 0 kudos
- 0 kudos
Hi @aranjan99, To add some detail to the earlier reply: the confusion here comes from the fact that the REST API and the Databricks CLI handle the "limit" parameter differently. REST API BEHAVIOR In the REST API (POST or GET to /api/2.1/jobs/runs/lis...
- 0 kudos

- 1252 Views
- 3 replies
- 2 kudos
Access Lab
Hi Team,How do I access lab? Do I need to take subscription?
- 1252 Views
- 3 replies
- 2 kudos
- 2 kudos
Hi @ShyamalaT, As @Advika and @szymon_dybczak mentioned, the hands-on labs that accompany Databricks Academy courses do require either an Instructor-Led Training (ILT) enrollment or a Databricks Academy Labs subscription. Here is a quick summary of y...
- 2 kudos
- 1595 Views
- 4 replies
- 0 kudos
Row count is higher than expected after breaking cases into 15-minute segments
I’m building a fact table in Databricks where the grain is one row per case per 15-minute segment. For example, if a case lasts 90 minutes, I expect about 6 rows.I generate the 15-minute segments and MERGE into a Delta table (incremental load). Howev...
- 1595 Views
- 4 replies
- 0 kudos
- 0 kudos
Hi @CuriousEngineer, This is a common scenario, and there are good solutions. Nice job including the code and the minimal reproducible example -- that makes it much easier to help. There are two places in your query that are very likely introducing d...
- 0 kudos
- 6917 Views
- 8 replies
- 2 kudos
Resolved! Continuous Job - How to set max_retries
Hello Community,I have a couple of continuous workflows (jobs) running in production, and they’ve been working well so far. However, we’re seeing some transient failures that are causing the entire job to restart — which I’d prefer to avoid.While we ...

- 6917 Views
- 8 replies
- 2 kudos
- 2 kudos
Hi @Kirankumarbs, Thanks for posting this. I can see from the thread that the existing replies confirmed the limitation but did not offer much in the way of alternatives. Let me provide a fuller picture. THE SHORT ANSWER You cannot set a custom max_r...
- 2 kudos

- 2918 Views
- 3 replies
- 4 kudos
Resolved! Where is Lakeflow Designer in the databricks UI
Hello everyone,Yesterday I saw a demo of Lakeflow Designer, and it looked very interesting. I tried to find this option in the UI, but I was not able to locate it.Could anyone please guide me on where I can access or try out this feature?I would real...
- 2918 Views
- 3 replies
- 4 kudos

- 4 kudos
If you are talking about the No-code version that is described here, then that is still in Private Preview as far as I am aware. Talk to your Databricks Account if you want to opt into the preview. If you do get access to it, you should be able to fi...
- 4 kudos
- 3119 Views
- 2 replies
- 3 kudos
Resolved! Share dashboard with external customers
I’m new to Databricks and still exploring the platform. One of our requirements is to share a Databricks dashboard with multiple external customers (for example, Customer 1 and Customer 2).The key requirement is data isolation:When a user from Custom...
- 3119 Views
- 2 replies
- 3 kudos
- 3 kudos
Hi @RJ1 - Welcome to Databricks Platform! Great question. This is a very common requirement. At a high level, you’ll want to separate the concerns: How users authenticate and are identified (who is the user / which customer are they from?)How data i...
- 3 kudos
- 1841 Views
- 3 replies
- 2 kudos
Resolved! Data governance solution
I am here looking for Data governance solution for organization. I also searched this on many different website and found many solutions. We are bit confused to which one to choose. One of my friend suggest me this platform, and i am hoping i will ge...
- 1841 Views
- 3 replies
- 2 kudos
- 2 kudos
You can use Unity Catalog for Databricks Lakehouse. You can use Collibra/Open Metadata along with Unity Catalog for complete governance
- 2 kudos
-
.CSV
1 -
Access Data
2 -
Access Databricks
3 -
Access Delta Tables
2 -
Account reset
1 -
adcAws databricks
1 -
ADF Pipeline
1 -
ADLS Gen2 With ABFSS
1 -
Advanced Data Engineering
2 -
AI
5 -
AIBI
1 -
Analytics
1 -
angelhack
1 -
Apache spark
1 -
Apache Spark 3.0
1 -
api
1 -
Api Calls
2 -
API Documentation
4 -
App
2 -
Application
2 -
Architecture
1 -
asset bundle
1 -
Asset Bundles
3 -
Auto-loader
1 -
Autoloader
4 -
Aws databricks
1 -
AWS security token
1 -
AWSDatabricksCluster
1 -
Azure
7 -
Azure data disk
1 -
Azure Data Factory
1 -
Azure databricks
16 -
Azure Databricks Delta Table
1 -
Azure Databricks Job
1 -
Azure Databricks SQL
6 -
Azure databricks workspace
1 -
Azure Unity Catalog
6 -
Azure-databricks
1 -
AzureDatabricks
1 -
AzureDevopsRepo
1 -
best practices
1 -
Big Data Solutions
1 -
Billing
1 -
Billing and Cost Management
2 -
Blackduck
1 -
Bronze Layer
1 -
Business Intelligence
1 -
CDC
1 -
Certification
3 -
Certification Exam
1 -
Certification Voucher
3 -
Chrome
1 -
CICDForDatabricksWorkflows
1 -
Cloud_files_state
1 -
CloudFiles
1 -
Cluster
3 -
Cluster Init Script
1 -
Comments
1 -
Community Edition
4 -
Community Edition Account
1 -
Community Event
1 -
Community Group
2 -
Community Members
1 -
CommunityArticle
1 -
Compute
3 -
Compute Instances
1 -
conditional tasks
1 -
Connection
1 -
consulting
2 -
Contest
1 -
Course
1 -
Credentials
1 -
csv
1 -
Custom Python
1 -
CustomLibrary
1 -
DAIS2026
1 -
Dashboards
1 -
Data
1 -
Data + AI Summit
1 -
Data Engineer Associate
1 -
Data Engineering
4 -
Data Explorer
1 -
Data Governance
1 -
Data Ingestion
1 -
Data Ingestion & connectivity
1 -
Data Ingestion Architecture
1 -
Data Processing
1 -
Data Quality
1 -
Data Quality Checks
1 -
DataArchitecture
1 -
Databrick add-on for Splunk
1 -
Databricks
6 -
Databricks Academy
1 -
Databricks AI + Data Summit
1 -
databricks ai gateway
1 -
Databricks Alerts
1 -
Databricks App
2 -
Databricks Assistant
1 -
Databricks autoloader
1 -
Databricks Certification
1 -
Databricks Certified
1 -
Databricks champion
1 -
Databricks Cluster
2 -
Databricks Clusters
1 -
Databricks Community
11 -
Databricks community edition
3 -
Databricks Community Edition Account
1 -
Databricks Community Post
1 -
Databricks Community Rewards Store
3 -
Databricks connect
1 -
Databricks Dashboard
3 -
Databricks delta
2 -
Databricks Delta Table
2 -
Databricks Demo Center
1 -
Databricks Documentation
4 -
Databricks Error Message
1 -
Databricks genAI associate
1 -
Databricks JDBC Driver
2 -
Databricks Job
1 -
Databricks Lakeflow
2 -
Databricks Lakehouse Platform
6 -
Databricks Migration
1 -
Databricks Model
1 -
Databricks notebook
2 -
Databricks Notebooks
4 -
Databricks Partner
1 -
Databricks Platform
2 -
Databricks Pyspark
1 -
Databricks Python Notebook
1 -
Databricks Repo
1 -
Databricks Runtime
1 -
Databricks Serverless
2 -
Databricks SQL
5 -
Databricks SQL Alerts
1 -
Databricks SQL Visualizations
1 -
Databricks SQL Warehouse
1 -
Databricks Terraform
1 -
Databricks UI
1 -
Databricks Unity Catalog
5 -
Databricks User Group
1 -
Databricks Workflow
2 -
Databricks Workflows
2 -
Databricks workspace
3 -
Databricks-connect
1 -
databricks_cluster_policy
1 -
DatabricksJobCluster
1 -
DataCleanroom
1 -
DataDays
1 -
DataEngineering
1 -
DataGovernance
1 -
Datagrip
1 -
DataMasking
2 -
DataVersioning
1 -
dbdemos
2 -
DBFS
1 -
DBRuntime
1 -
DBSQL
1 -
DDL
1 -
Dear Community
1 -
deduplication
1 -
Delt Lake
1 -
Delta Live Pipeline
3 -
Delta Live Table
5 -
Delta Live Table Pipeline
5 -
Delta Live Table Pipelines
4 -
Delta Live Tables
7 -
Delta Sharing
2 -
Delta Time Travel
1 -
deltaSharing
1 -
Deny assignment
1 -
Development
1 -
DevOps
1 -
DLT
10 -
DLT Pipeline
7 -
DLT Pipelines
5 -
Dolly
1 -
Download files
1 -
DQX
2 -
Dynamic Variables
1 -
Engineering With Databricks
1 -
env
1 -
ETL Pipelines
1 -
Event Driven
1 -
External Sources
1 -
External Storage
2 -
FAQ for Databricks Learning Festival
2 -
Feature Store
2 -
File Trigger
1 -
Filenotfoundexception
1 -
Free Edition
1 -
Free trial
1 -
friendsofcommunity
1 -
GCP Databricks
1 -
GenAI
2 -
GenAI and LLMs
1 -
GenAI Course Material
1 -
genie
2 -
Genie Agents
2 -
Getting started
3 -
Google Bigquery
1 -
Grafana
1 -
helpme
1 -
HIPAA
1 -
Hubert Dudek
2 -
IA
1 -
import
2 -
Integration
1 -
ISVPartnership
1 -
JDBC Connections
1 -
JDBC Connector
1 -
Job Task
1 -
JSON Object
1 -
Lake Flow Connect
1 -
Lakeflow Pipelines
1 -
LakeflowDesigner
1 -
Lakehouse
1 -
Learning
2 -
Lineage
1 -
link for labs
1 -
LLM
1 -
Login
1 -
Login Account
1 -
Login Issue
1 -
Machine Learning
3 -
MachineLearning
1 -
Market Place
1 -
MasterDataManagement
1 -
Materialized Tables
2 -
MDM
1 -
Medallion Architecture
1 -
meetup
2 -
Memory
1 -
Memory error
1 -
Memory management
1 -
Metadata
1 -
Migration
1 -
ML Model
2 -
MlFlow
2 -
Model
1 -
Model Serving
1 -
Model Training
1 -
Module
1 -
Monitoring
1 -
mosic ai search
1 -
Networking
2 -
Notebook
1 -
Onboarding
1 -
Onboarding Trainings
1 -
OOM Error
1 -
OpenAI
1 -
Pandas udf
1 -
Permissions
1 -
personalcompute
1 -
Pipeline
2 -
Plotly
1 -
plugins
1 -
PostgresSQL
1 -
Pricing
1 -
provisioned throughput
1 -
Pyspark
1 -
Python
5 -
Python Code
1 -
Python Wheel
1 -
Quickstart
1 -
Read data
1 -
Repos Support
1 -
Reset
1 -
Rewards Store
2 -
Salesforce with Databricks
1 -
Sant
1 -
Schedule
1 -
Security
1 -
serverless
3 -
serving endpoint
1 -
Session
1 -
Sign Up Issues
2 -
Software Development
1 -
Spark
1 -
Spark Connect
1 -
Spark scala
1 -
sparkui
2 -
Speakers
1 -
Splunk
2 -
SQL
8 -
SQL Visualizations
1 -
streamlit
1 -
Summit23
7 -
Support Tickets
1 -
Sydney
2 -
Table Download
1 -
Tags
3 -
terraform
1 -
Training
2 -
Troubleshooting
1 -
Unity Catalog
4 -
Unity Catalog Metastore
2 -
Unity Gateway
1 -
UnityCatalog
1 -
Update
1 -
user groups
2 -
Venicold
3 -
Vnet
1 -
Voucher Not Recieved
1 -
VScode Extension
1 -
vulnerability
1 -
Watermark
1 -
Webinar
1 -
Weekly Documentation Update
1 -
Weekly Release Notes
2 -
Women
1 -
Workflow
2 -
Workspace
3
- « Previous
- Next »
| User | Count |
|---|---|
| 142 | |
| 123 | |
| 57 | |
| 46 | |
| 40 |


