
- 918 Views
- 1 replies
- 1 kudos
Resolved! Databricks Dashboard Issue: No Mouse-Based Navigation When Dashboard Tabs Exceed the Top Ribbon
When dashboards have many pages, the top tab bar overflows and can’t be navigated using the mouse. Only left keyboard arrow, right keyboard arrow works, which is slow and inconvenient not user friendly.Expected: ability to scroll tabs with mouse e.g....
- 918 Views
- 1 replies
- 1 kudos
- 1 kudos
Hello @surajitDE! You can use the horizontal scroll bar to navigate through the dashboard pages.If you’re on a trackpad, you can simply scroll horizontally. If you’re using a mouse, you can: Hold Shift and scroll with the mouse wheel (easiest), orDra...
- 1 kudos
- 7510 Views
- 4 replies
- 6 kudos
Resolved! How to use variable-overrides.json for environment-specific configuration in Asset Bundles?
Hi all,Could someone clarify the intended usage of the variable-overrides.json file in Databricks Asset Bundles?Let me give some context. Let's say my repository layout looks like this:databricks/ ├── notebooks/ │ └── notebook.ipynb ├── resources/ ...
- 7510 Views
- 4 replies
- 6 kudos
- 6 kudos
It does. Thanks for the reponse. I also continued playing around with it and found a way using the variable-overrides.json file. I'll leave it here just in case anyone is interested:Repository layout:databricks/ ├── notebooks/ │ └── notebook.ipynb ...
- 6 kudos
- 4222 Views
- 4 replies
- 1 kudos
Best practices for optimizing Spark jobs
What are some best practices for optimizing Spark jobs in Databricks, especially when dealing large datasets? Any tips or resources would be greatly appreciated! I’m trying to analyze data on restaurant menu prices so that insights would be especiall...
- 4222 Views
- 4 replies
- 1 kudos

- 1 kudos
In addition to above cool comments, try to use clusters with VMs enabled for disk caching as well. This caches data at parquet files level in VM local storage, acting as a great complement to spark caching.
- 1 kudos

- 768 Views
- 0 replies
- 1 kudos
Agent Bricks Webinar
Our Databricks x Unifeye Meetup community just hit 150 members! A huge milestone, especially considering we’ve consistently had 50+ people joining every webinar. The momentum is real, and the audience keeps growing! This week, we’re taking it one s...

- 768 Views
- 0 replies
- 1 kudos
- 3608 Views
- 2 replies
- 1 kudos
Resolved! SQL cell v spark.sql in notebooks
I am fairly new to Databricks, and indeed Python, so apologies if this has been answered elsewhere but I've been unable to find it.I have been mainly working in notebooks as opposed to the SQL editor, but coding in SQL where possible using SQL cells ...
- 3608 Views
- 2 replies
- 1 kudos
- 1 kudos
Thanks Louis, really good explanation and helpful examples!
- 1 kudos
- 9913 Views
- 5 replies
- 3 kudos
Connect to Onelake using Service Principal, Unity Catalog and Databricks Access Connector
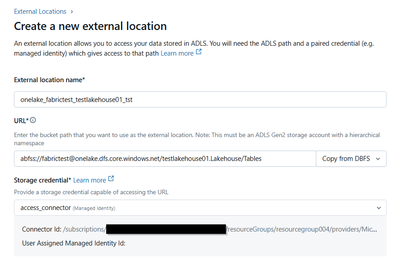
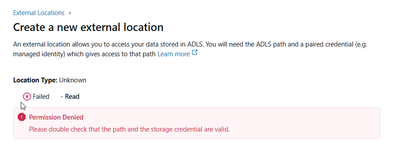
We are trying to connect Databricks to OneLake, to read data from a Fabric workspace into Databricks, using a notebook. We also use Unity Catalog. We are able to read data from the workspace with a Service Principal like this:from pyspark.sql.types i...
- 9913 Views
- 5 replies
- 3 kudos
- 3 kudos
As commented you need to assign "Storage Blob Data Contributor or Storage Account Contributor to the service principal you're using in the "connection" provided to the "external location". Another more advanced and even better option would be to use ...
- 3 kudos
- 5488 Views
- 1 replies
- 0 kudos
Updating a Delta Table in Delta Live Tables (DLT) from Two Event Hubs
I am working with Databricks Delta Live Tables (DLT) and need to ingest data from two different Event Hubs. My goal is to:Ingest initial data from the first Event Hub (Predictor) and store it in a Delta Table (data_predictions).Later, update this tab...
- 5488 Views
- 1 replies
- 0 kudos
- 0 kudos
To achieve robust, persistent CDC (Change Data Capture)–style updates in Databricks DLT with your scenario—while keeping data_predictions as a Delta Table (not a Materialized View)—you need to carefully avoid streaming joins and side effects across s...
- 0 kudos
- 4486 Views
- 1 replies
- 1 kudos
Resolved! Databricks UMF Best Practice
Hi there, I would like to get some feedback on what are the ideal/suggested ways to get UMF data from our Azure cloud into Databricks. For context, UMF can mean either:User Managed FileUser Maintained FileBasically, a UMF could be something like a si...
- 4486 Views
- 1 replies
- 1 kudos
- 1 kudos
Several effective patterns exist for ingesting User Managed Files (UMF) such as CSVs from Azure into Databricks, each with different trade-offs depending on governance, user interface preferences, and integration with Microsoft 365 services. Common A...
- 1 kudos
- 5223 Views
- 1 replies
- 0 kudos
DLT detecting changes but not applying them
We have three source tables used for a streaming dimension table in silver. Around 50K records are changed in one of the source tables, and the DLT pipeline shows that it has updated those 50K records, but they remain unchanged. The only way to pick ...
- 5223 Views
- 1 replies
- 0 kudos
- 0 kudos
The most likely reason your DLT pipeline shows 50K updates but the records remain unchanged is related to how Delta Live Tables (DLT) handle streaming tables, update logic, and schema constraints. When the target table uses an auto-increment ID (espe...
- 0 kudos
- 4174 Views
- 1 replies
- 0 kudos
Issue with Disabled "Repair DAG", "Repair All DAGs" Buttons in Airflow UI, functionality is working.
We are encountering an issue in the Airflow UI where the 'Repair DAG' and 'Repair All DAGs' options are disabled when a specific task fails. While the repair functionality itself is working properly (i.e., the DAGs can still be repaired through execu...
- 4174 Views
- 1 replies
- 0 kudos
- 0 kudos
The issue with the 'Repair DAG' and 'Repair All DAGs' options being disabled in the Airflow UI when using the Databricks Workflow Operator is a known UI-specific problem that does not affect backend execution or the actual repair functionality. While...
- 0 kudos
- 7022 Views
- 1 replies
- 1 kudos
How to Fetch Azure OpenAI api_version and engine Dynamically After Resource Creation via Python?
Hello,I am using Python to automate the creation of Azure OpenAI resources via the Azure Management API. I am successfully able to create the resource, but I need to dynamically fetch the following details after the resource is created:API Version (a...
- 7022 Views
- 1 replies
- 1 kudos
- 1 kudos
Hi Sudheer, It's been a while since you posted, but are you still facing this issue? Here are a few things you could check if needed: API version In Azure OpenAI, api-version is a query parameter on the data-plane (inference) requests, not a proper...
- 1 kudos
- 2515 Views
- 5 replies
- 2 kudos
Resolved! #data bricks snowflake dialect
Hello,I’m encountering an issue while converting SQL code to the Lake bridge Snowflake dialect. It seems that DML and DDL statements may not be supported in the Snowflake dialect within Lake bridge.Could you please confirm whether DML and DDL stateme...
- 2515 Views
- 5 replies
- 2 kudos

- 2 kudos
@jadhav_vikas , I did some digging through internal docs and I have some hints/suggestions. Short answer Databricks Lakehouse Federation (often referred to as “Lakehouse Bridge”) provides read‑only access to Snowflake; DML and DDL are not supported ...
- 2 kudos

- 1367 Views
- 3 replies
- 0 kudos
Resolved! API call fails to initiate create Service Principal secret
Hi,I've constructed an AWS lambda function which is used to auto rotate my Service Principal Secret in the Databricks account. Authentication is setup with OAuth2, the api call for the token generation is successful but when executing the api call to...
- 1367 Views
- 3 replies
- 0 kudos
- 0 kudos
Your error message, "Invalid service principal id," typically indicates a mismatch or formatting problem with the service principal's unique identifier in your API request. Although you checked the client_id, this value is not always the one needed f...
- 0 kudos
- 1417 Views
- 1 replies
- 2 kudos
Databricks Taiwan User Community
Would be great have a group for databricks Taiwan community.
- 1417 Views
- 1 replies
- 2 kudos
- 2 kudos
Hey @kennyhsieh , hope it's not too late to reply to the post! A "Databricks User Group Taiwan" has recently been formed on LinkedIn.
- 2 kudos
- 4686 Views
- 2 replies
- 0 kudos
Can AWS workspaces share subnets?
The docs state:"You can choose to share one subnet across multiple workspaces or both subnets across workspaces."as well as:"You can reuse existing security groups rather than create new ones."and on this page:"If you plan to share a VPC and subnets ...
- 4686 Views
- 2 replies
- 0 kudos
- 0 kudos
AWS WorkSpaces can be configured with subnets that can be shared within an AWS account or across AWS accounts using resource sharing mechanisms, but this depends on the specific AWS service and context. For Databricks workspaces on AWS, documentation...
- 0 kudos
-
.CSV
1 -
Access Data
2 -
Access Databricks
3 -
Access Delta Tables
3 -
Account reset
1 -
adcAws databricks
1 -
ADF Pipeline
1 -
ADLS Gen2 With ABFSS
1 -
Advanced Data Engineering
2 -
AI
5 -
AIBI
1 -
Analytics
1 -
Apache spark
1 -
Apache Spark 3.0
1 -
api
1 -
Api Calls
2 -
API Documentation
4 -
App
2 -
Application
2 -
Architecture
1 -
asset bundle
1 -
Asset Bundles
3 -
Auto-loader
1 -
Autoloader
4 -
Aws databricks
1 -
AWS security token
1 -
AWSDatabricksCluster
1 -
Azure
7 -
Azure data disk
1 -
Azure Data Factory
1 -
Azure databricks
16 -
Azure Databricks Delta Table
1 -
Azure Databricks Job
1 -
Azure Databricks SQL
6 -
Azure databricks workspace
1 -
Azure Unity Catalog
6 -
Azure-databricks
1 -
AzureDatabricks
1 -
AzureDevopsRepo
1 -
best practices
1 -
Big Data Solutions
1 -
Billing
1 -
Billing and Cost Management
2 -
Blackduck
1 -
Bronze Layer
1 -
Business Intelligence
1 -
CDC
1 -
Certification
3 -
Certification Exam
1 -
Certification Voucher
3 -
Chrome
1 -
CICDForDatabricksWorkflows
1 -
Cloud_files_state
1 -
CloudFiles
1 -
Cluster
3 -
Cluster Init Script
1 -
Comments
1 -
Community Edition
4 -
Community Edition Account
1 -
Community Event
1 -
Community Group
2 -
Community Members
1 -
CommunityArticle
1 -
Compute
3 -
Compute Instances
1 -
conditional tasks
1 -
Connection
1 -
consulting
2 -
Contest
1 -
Course
1 -
Credentials
1 -
csv
1 -
Custom Python
1 -
CustomLibrary
1 -
DAIS2026
1 -
Dashboards
1 -
Data
1 -
Data + AI Summit
1 -
Data Engineer Associate
1 -
Data Engineering
4 -
Data Explorer
1 -
Data Governance
1 -
Data Ingestion
1 -
Data Ingestion & connectivity
1 -
Data Ingestion Architecture
1 -
Data Processing
1 -
Data Quality
1 -
Data Quality Checks
1 -
DataArchitecture
1 -
Databrick add-on for Splunk
1 -
databricks
6 -
Databricks Academy
1 -
Databricks AI + Data Summit
1 -
Databricks Alerts
1 -
Databricks App
2 -
Databricks Assistant
1 -
Databricks autoloader
1 -
Databricks Certification
1 -
Databricks Certified
1 -
Databricks champion
1 -
Databricks Cluster
2 -
Databricks Clusters
1 -
Databricks Community
11 -
Databricks community edition
3 -
Databricks Community Edition Account
1 -
Databricks Community Post
1 -
Databricks Community Rewards Store
3 -
Databricks connect
1 -
Databricks Dashboard
3 -
Databricks delta
2 -
Databricks Delta Table
2 -
Databricks Demo Center
1 -
Databricks Documentation
4 -
Databricks Error Message
1 -
Databricks genAI associate
1 -
Databricks JDBC Driver
2 -
Databricks Job
1 -
Databricks Lakeflow
2 -
Databricks Lakehouse Platform
6 -
Databricks Migration
1 -
Databricks Model
1 -
Databricks notebook
2 -
Databricks Notebooks
4 -
Databricks Partner
1 -
Databricks Platform
2 -
Databricks Pyspark
1 -
Databricks Python Notebook
1 -
Databricks Repo
1 -
Databricks Runtime
1 -
Databricks Serverless
2 -
Databricks SQL
5 -
Databricks SQL Alerts
1 -
Databricks SQL Visualizations
1 -
Databricks SQL Warehouse
1 -
Databricks Terraform
1 -
Databricks UI
1 -
Databricks Unity Catalog
5 -
Databricks User Group
1 -
Databricks Workflow
2 -
Databricks Workflows
2 -
Databricks workspace
3 -
Databricks-connect
1 -
databricks_cluster_policy
1 -
DatabricksJobCluster
1 -
DataCleanroom
1 -
DataDays
1 -
DataEngineering
1 -
DataGovernance
1 -
Datagrip
1 -
DataMasking
2 -
DataVersioning
1 -
dbdemos
2 -
DBFS
1 -
DBRuntime
1 -
DBSQL
1 -
DDL
1 -
Dear Community
1 -
deduplication
1 -
Delt Lake
1 -
Delta Live Pipeline
3 -
Delta Live Table
5 -
Delta Live Table Pipeline
5 -
Delta Live Table Pipelines
4 -
Delta Live Tables
7 -
Delta Sharing
2 -
Delta Time Travel
1 -
deltaSharing
1 -
Deny assignment
1 -
Development
1 -
DevOps
1 -
DLT
10 -
DLT Pipeline
7 -
DLT Pipelines
5 -
Dolly
1 -
Download files
1 -
DQX
2 -
Dynamic Variables
1 -
Engineering With Databricks
1 -
env
1 -
ETL Pipelines
1 -
Event Driven
1 -
External Sources
1 -
External Storage
2 -
FAQ for Databricks Learning Festival
2 -
Feature Store
2 -
File Trigger
1 -
Filenotfoundexception
1 -
Free Edition
1 -
Free trial
1 -
friendsofcommunity
1 -
GCP Databricks
1 -
GenAI
2 -
GenAI and LLMs
1 -
GenAI Course Material
1 -
Genie
2 -
Genie Agents
2 -
Getting started
3 -
Google Bigquery
1 -
Grafana
1 -
helpme
1 -
HIPAA
1 -
Hubert Dudek
2 -
IA
1 -
import
2 -
Integration
1 -
ISVPartnership
1 -
JDBC Connections
1 -
JDBC Connector
1 -
Job Task
1 -
JSON Object
1 -
Lake Flow Connect
1 -
Lakeflow Pipelines
1 -
LakeflowDesigner
1 -
Lakehouse
1 -
Learning
2 -
Lineage
1 -
link for labs
1 -
LLM
1 -
Login
1 -
Login Account
1 -
Login Issue
1 -
Machine Learning
3 -
MachineLearning
1 -
Market Place
1 -
MasterDataManagement
1 -
Materialized Tables
2 -
MDM
1 -
Medallion Architecture
1 -
meetup
2 -
Metadata
1 -
Migration
1 -
ML Model
2 -
MlFlow
2 -
Model
1 -
Model Serving
1 -
Model Training
1 -
Module
1 -
Monitoring
1 -
mosic ai search
1 -
Networking
2 -
Notebook
1 -
Onboarding
1 -
Onboarding Trainings
1 -
OpenAI
1 -
Pandas udf
1 -
Permissions
1 -
personalcompute
1 -
Pipeline
2 -
Plotly
1 -
plugins
1 -
PostgresSQL
1 -
Pricing
1 -
provisioned throughput
1 -
Pyspark
1 -
Python
5 -
Python Code
1 -
Python Wheel
1 -
Quickstart
1 -
Read data
1 -
Repos Support
1 -
Reset
1 -
Rewards Store
2 -
Salesforce with Databricks
1 -
Sant
1 -
Schedule
1 -
Serverless
3 -
serving endpoint
1 -
Session
1 -
Sign Up Issues
2 -
Software Development
1 -
Spark
1 -
Spark Connect
1 -
Spark scala
1 -
sparkui
2 -
Speakers
1 -
Splunk
2 -
SQL
8 -
SQL Visualizations
1 -
streamlit
1 -
Summit23
7 -
Support Tickets
1 -
Sydney
2 -
Table Download
1 -
Tags
3 -
terraform
1 -
Training
2 -
Troubleshooting
1 -
Unity Catalog
4 -
Unity Catalog Metastore
2 -
UnityCatalog
1 -
Update
1 -
user groups
2 -
Venicold
3 -
Vnet
1 -
Voucher Not Recieved
1 -
VScode Extension
1 -
Watermark
1 -
Webinar
1 -
Weekly Documentation Update
1 -
Weekly Release Notes
2 -
Women
1 -
Workflow
2 -
Workspace
3
- « Previous
- Next »
| User | Count |
|---|---|
| 142 | |
| 123 | |
| 57 | |
| 46 | |
| 40 |


