
- 29096 Views
- 2 replies
- 1 kudos
Resolved! Deny assignment modification to allow attach/detach of disks in azure databricks
Our application does storage autoscaling on Azure. We would like to deploy our solution with Azure databricks. But even though the service principal associated with our application has the necessary roles and permissions to attach/detach a disk from ...
- 29096 Views
- 2 replies
- 1 kudos
- 1 kudos
Thank you for your replyIs there any way databricks provides to bypass the deny assignment for specific apps? I noticed in the deny assignment unity-catalog-access-connector has been provided exlusion under the excludePrincipals section. is there a w...
- 1 kudos
- 2107 Views
- 1 replies
- 0 kudos
Create persistent Scala UDF
I've created a UDF in Scala (using Databricks notebook) which checks if the value of a field in a table is greater than 0, then sum those values. UDF is working as expected. The problem is, that this UDF will be used by multiple SQLs across different...
- 2107 Views
- 1 replies
- 0 kudos
- 0 kudos
In the child notebook:def my_udf(x): return x + 1 spark.udf.register("my_udf", my_udf) dbutils.notebook.exit(my_udf)In the master notebook:child_udf = dbutils.notebook.run("PathToChildnotebook", timeout_seconds=600) spark.udf.register("my_udf",...
- 0 kudos
- 5341 Views
- 3 replies
- 1 kudos
[UNBOUND_SQL_PARAMETER] When running Placeholder query
I am using the databricks-sql-go library version 1.5.2. I am trying to run a query with placeholders of type '?'The query looks like params, args := databricksParams(values)sql := fmt.Sprintf(`SELECT COUNT(*) FROM %s.%s WHERE %s IN (%s)`, schema, tab...
- 5341 Views
- 3 replies
- 1 kudos

- 1 kudos
Can you print out an example after the Sprintf substitutions?It seems you generated a query with a named parameter: ":_58" But args (which should be a Map) does not have a key named "_58".
- 1 kudos
- 3203 Views
- 1 replies
- 0 kudos
DLT: Only STREAMING tables can have multiple queries.
I am trying to to do a one-time back-fill on a DLT table following the example here: dlt.table() def test(): # providing a starting version return (spark.readStream.format("delta") .option("readChangeFeed", "true") .option("...
- 3203 Views
- 1 replies
- 0 kudos
- 0 kudos
I should also add that when I drop the `backfill` function, validation happens successfully and we get the following pipeline DAG:
- 0 kudos

- 14335 Views
- 1 replies
- 1 kudos
Introducing AI Model Sharing with Databricks!
Today, we're excited to announce that AI model sharing is available in both Databricks Delta Sharing and on the Databricks Marketplace. With Delta Sharing you can now easily share and serve AI models securely within your organization or externally ac...

- 14335 Views
- 1 replies
- 1 kudos
- 1 kudos
I'm eager to dive in and leverage these new features to elevate my AI game with Databricks.This is Johnson from KBS Technologies.Thanks for your update.
- 1 kudos
- 4759 Views
- 3 replies
- 0 kudos
Cannot create a repo because the parent path does not exist
I tried following this docWork With Large Monorepos With Sparse Checkout Support in Databricks Repos | Databricks BlogWhen I hook it up to my repos using Azure DevOps Services and check mark Sparse checkout mode, I pass in a subdirectory in my Cone p...
- 4759 Views
- 3 replies
- 0 kudos
- 12203 Views
- 2 replies
- 0 kudos
Resolved! Show Existing Header From CSV I External Table
Hello, is there a way to load csv data into an external table without the _c0, _c1 columns showing?
- 12203 Views
- 2 replies
- 0 kudos
- 0 kudos
My question was answered in a separate thread here.
- 0 kudos
- 5618 Views
- 3 replies
- 0 kudos
Resolved! Unable to load csv data with correct header values in External tables
Hello, is there a way to load "CSV" data into an external table without the _c0, _c1 columns showing?I've tried using the options within the sql statement that does not appear to work.Which results in this table


- 5618 Views
- 3 replies
- 0 kudos
- 0 kudos
you need set "USING data_source"https://community.databricks.com/t5/data-engineering/create-external-table-using-multiple-paths-locations/td-p/44042
- 0 kudos
- 2301 Views
- 1 replies
- 0 kudos
What is the REST API payload for "not sending alert when alert is back to normal"?
Greeting,I am using REST API to create & schedule sql alert by default these alerts will send notifications when they are back to normal which I don't want, In the UI I have the option to uncheck the box (shown in the picture) but I can't find any do...

- 2301 Views
- 1 replies
- 0 kudos

- 0 kudos
@Lambda Did you refer this documentation: https://docs.databricks.com/api/workspace/alerts/create
- 0 kudos
- 2562 Views
- 1 replies
- 0 kudos
Spark VCore for Databrick vCPU
Hi Team,What is the equivalent Spark VCore for Databrick vCPU? , like for below example for DS3 v2 , vCPU=4 and RAM = 14.00 GiB, would like to know equivalent Spark VCore for DS3 v2 as in Azure Databricks Pricing | Microsoft AzureRegards,Phanindra
- 2562 Views
- 1 replies
- 0 kudos
- 0 kudos
@Phani1 In Databricks, the vCPU count is equivalent to the number of Spark vCores. This means that if the DS3 v2 instance has 4 vCPU, it would also have 4 Spark vCores. Please note that the Spark VCore count is based on the vCPU count of the underlyi...
- 0 kudos
- 2026 Views
- 1 replies
- 0 kudos
Can't enter 'edit mode' using shortcut
Hi,With the recently added AI Assistant to databricks notebooks, I'm having issues entering the 'edit mode' of a notebook cell. Previously, I could simply press the 'Enter' key in order to do this but this no longer works.Is anyone else having the sa...
- 2026 Views
- 1 replies
- 0 kudos
- 0 kudos
@AtomicBoy99, it seems like the fix is in place. Can you confirm if it is working well now?
- 0 kudos
- 5464 Views
- 2 replies
- 0 kudos
Python Logging cant save log in DBFS
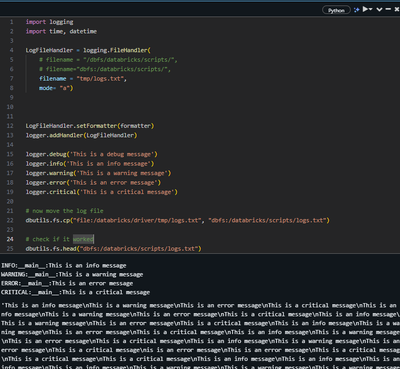
Hi! I am trying to integrate logging into my project. Got the library and logs to work but cant log the file into DBFS directly.Have any of you been able to save and append the log file directly to dbfs? From what i came across online the best way to...
- 5464 Views
- 2 replies
- 0 kudos
- 0 kudos
you can use azure_storage_loggingSet Python Logging to Azure Blob, but Can not Find Log File there - Stack Overflow
- 0 kudos
- 8510 Views
- 2 replies
- 1 kudos
Databricks notebook how to stop truncating numbers when export the query result to csv
I use Databricks notebook to query databases and export / download result to csv. I just accidentally close a pop-up window asking if need to truncate the numbers, I accidentally chose yes and don't ask again. Now all my long digit numbers are trunca...
- 8510 Views
- 2 replies
- 1 kudos
- 1 kudos
@Jasonh202222 - Kindly check the below navigation path user settings -> Account settings -> Display -> Download and Export. Under Download and Export, Enable the checkbox - "Prompt for formatting large numbers when downloading or exporting" and cl...
- 1 kudos
- 9360 Views
- 2 replies
- 1 kudos
Resolved! Difference between username and account_id
I have a web app that can read files from a person's cloud-based drive (e.g., OneDrive, Google Drive, Dropbox). The app gets access to the files using OAuth2. The app only ever has access to the files for that user. Part of the configuration requir...
- 9360 Views
- 2 replies
- 1 kudos
- 1 kudos
The provided links were helpful. The take-away* usernames are "globally" unique to an individual; the username is the person's email.* a username can be associated with up to 50 accounts; account_ids track the resources available to the user.This cl...
- 1 kudos
- 3940 Views
- 0 replies
- 0 kudos
Using streaming data received from Pub/sub topic
I have a notebook in Databricks in which I am streaming a Pub/sub topic. The code for this looks like following-%pip install --upgrade google-cloud-pubsub[pandas] from pyspark.sql import SparkSession authOptions={"clientId" : "123","clientEmail"...
- 3940 Views
- 0 replies
- 0 kudos
-
.CSV
1 -
Access Data
2 -
Access Databricks
3 -
Access Delta Tables
2 -
Account reset
1 -
adcAws databricks
1 -
ADF Pipeline
1 -
ADLS Gen2 With ABFSS
1 -
Advanced Data Engineering
2 -
AI
5 -
AIBI
1 -
Analytics
1 -
angelhack
1 -
Apache spark
1 -
Apache Spark 3.0
1 -
api
1 -
Api Calls
2 -
API Documentation
4 -
App
2 -
Application
2 -
Architecture
1 -
asset bundle
1 -
Asset Bundles
3 -
Auto-loader
1 -
Autoloader
4 -
Aws databricks
1 -
AWS security token
1 -
AWSDatabricksCluster
1 -
Azure
7 -
Azure data disk
1 -
Azure Data Factory
1 -
Azure databricks
16 -
Azure Databricks Delta Table
1 -
Azure Databricks Job
1 -
Azure Databricks SQL
6 -
Azure databricks workspace
1 -
Azure Unity Catalog
6 -
Azure-databricks
1 -
AzureDatabricks
1 -
AzureDevopsRepo
1 -
best practices
1 -
Big Data Solutions
1 -
Billing
1 -
Billing and Cost Management
2 -
Blackduck
1 -
Bronze Layer
1 -
Business Intelligence
1 -
CDC
1 -
Certification
3 -
Certification Exam
1 -
Certification Voucher
3 -
Chrome
1 -
CICDForDatabricksWorkflows
1 -
Cloud_files_state
1 -
CloudFiles
1 -
Cluster
3 -
Cluster Init Script
1 -
Comments
1 -
Community Edition
4 -
Community Edition Account
1 -
Community Event
1 -
Community Group
2 -
Community Members
1 -
CommunityArticle
1 -
Compute
3 -
Compute Instances
1 -
conditional tasks
1 -
Connection
1 -
consulting
2 -
Contest
1 -
Course
1 -
Credentials
1 -
csv
1 -
Custom Python
1 -
CustomLibrary
1 -
DAIS2026
1 -
Dashboards
1 -
Data
1 -
Data + AI Summit
1 -
Data Engineer Associate
1 -
Data Engineering
4 -
Data Explorer
1 -
Data Governance
1 -
Data Ingestion
1 -
Data Ingestion & connectivity
1 -
Data Ingestion Architecture
1 -
Data Processing
1 -
Data Quality
1 -
Data Quality Checks
1 -
DataArchitecture
1 -
Databrick add-on for Splunk
1 -
databricks
6 -
Databricks Academy
1 -
Databricks AI + Data Summit
1 -
databricks ai gateway
1 -
Databricks Alerts
1 -
Databricks App
2 -
Databricks Assistant
1 -
Databricks autoloader
1 -
Databricks Certification
1 -
Databricks Certified
1 -
Databricks champion
1 -
Databricks Cluster
2 -
Databricks Clusters
1 -
Databricks Community
11 -
Databricks community edition
3 -
Databricks Community Edition Account
1 -
Databricks Community Post
1 -
Databricks Community Rewards Store
3 -
Databricks connect
1 -
Databricks Dashboard
3 -
Databricks delta
2 -
Databricks Delta Table
2 -
Databricks Demo Center
1 -
Databricks Documentation
4 -
Databricks Error Message
1 -
Databricks genAI associate
1 -
Databricks JDBC Driver
2 -
Databricks Job
1 -
Databricks Lakeflow
2 -
Databricks Lakehouse Platform
6 -
Databricks Migration
1 -
Databricks Model
1 -
Databricks notebook
2 -
Databricks Notebooks
4 -
Databricks Partner
1 -
Databricks Platform
2 -
Databricks Pyspark
1 -
Databricks Python Notebook
1 -
Databricks Repo
1 -
Databricks Runtime
1 -
Databricks Serverless
2 -
Databricks SQL
5 -
Databricks SQL Alerts
1 -
Databricks SQL Visualizations
1 -
Databricks SQL Warehouse
1 -
Databricks Terraform
1 -
Databricks UI
1 -
Databricks Unity Catalog
5 -
Databricks User Group
1 -
Databricks Workflow
2 -
Databricks Workflows
2 -
Databricks workspace
3 -
Databricks-connect
1 -
databricks_cluster_policy
1 -
DatabricksJobCluster
1 -
DataCleanroom
1 -
DataDays
1 -
DataEngineering
1 -
DataGovernance
1 -
Datagrip
1 -
DataMasking
2 -
DataVersioning
1 -
dbdemos
2 -
DBFS
1 -
DBRuntime
1 -
DBSQL
1 -
DDL
1 -
Dear Community
1 -
deduplication
1 -
Delt Lake
1 -
Delta Live Pipeline
3 -
Delta Live Table
5 -
Delta Live Table Pipeline
5 -
Delta Live Table Pipelines
4 -
Delta Live Tables
7 -
Delta Sharing
2 -
Delta Time Travel
1 -
deltaSharing
1 -
Deny assignment
1 -
Development
1 -
DevOps
1 -
DLT
10 -
DLT Pipeline
7 -
DLT Pipelines
5 -
Dolly
1 -
Download files
1 -
DQX
2 -
Dynamic Variables
1 -
Engineering With Databricks
1 -
env
1 -
ETL Pipelines
1 -
Event Driven
1 -
External Sources
1 -
External Storage
2 -
FAQ for Databricks Learning Festival
2 -
Feature Store
2 -
File Trigger
1 -
Filenotfoundexception
1 -
Free Edition
1 -
Free trial
1 -
friendsofcommunity
1 -
GCP Databricks
1 -
GenAI
2 -
GenAI and LLMs
1 -
GenAI Course Material
1 -
Genie
2 -
Genie Agents
2 -
Getting started
3 -
Google Bigquery
1 -
Grafana
1 -
helpme
1 -
HIPAA
1 -
Hubert Dudek
2 -
IA
1 -
import
2 -
Integration
1 -
ISVPartnership
1 -
JDBC Connections
1 -
JDBC Connector
1 -
Job Task
1 -
JSON Object
1 -
Lake Flow Connect
1 -
Lakeflow Pipelines
1 -
LakeflowDesigner
1 -
Lakehouse
1 -
Learning
2 -
Lineage
1 -
link for labs
1 -
LLM
1 -
Login
1 -
Login Account
1 -
Login Issue
1 -
Machine Learning
3 -
MachineLearning
1 -
Market Place
1 -
MasterDataManagement
1 -
Materialized Tables
2 -
MDM
1 -
Medallion Architecture
1 -
meetup
2 -
Metadata
1 -
Migration
1 -
ML Model
2 -
MlFlow
2 -
Model
1 -
Model Serving
1 -
Model Training
1 -
Module
1 -
Monitoring
1 -
mosic ai search
1 -
Networking
2 -
Notebook
1 -
Onboarding
1 -
Onboarding Trainings
1 -
OpenAI
1 -
Pandas udf
1 -
Permissions
1 -
personalcompute
1 -
Pipeline
2 -
Plotly
1 -
plugins
1 -
PostgresSQL
1 -
Pricing
1 -
provisioned throughput
1 -
Pyspark
1 -
Python
5 -
Python Code
1 -
Python Wheel
1 -
Quickstart
1 -
Read data
1 -
Repos Support
1 -
Reset
1 -
Rewards Store
2 -
Salesforce with Databricks
1 -
Sant
1 -
Schedule
1 -
Security
1 -
Serverless
3 -
serving endpoint
1 -
Session
1 -
Sign Up Issues
2 -
Software Development
1 -
Spark
1 -
Spark Connect
1 -
Spark scala
1 -
sparkui
2 -
Speakers
1 -
Splunk
2 -
SQL
8 -
SQL Visualizations
1 -
streamlit
1 -
Summit23
7 -
Support Tickets
1 -
Sydney
2 -
Table Download
1 -
Tags
3 -
terraform
1 -
Training
2 -
Troubleshooting
1 -
Unity Catalog
4 -
Unity Catalog Metastore
2 -
Unity Gateway
1 -
UnityCatalog
1 -
Update
1 -
user groups
2 -
Venicold
3 -
Vnet
1 -
Voucher Not Recieved
1 -
VScode Extension
1 -
vulnerability
1 -
Watermark
1 -
Webinar
1 -
Weekly Documentation Update
1 -
Weekly Release Notes
2 -
Women
1 -
Workflow
2 -
Workspace
3
- « Previous
- Next »
| User | Count |
|---|---|
| 142 | |
| 123 | |
| 57 | |
| 46 | |
| 40 |


