

- 295 Views
- 2 replies
- 2 kudos
Image Annotation
What is Image Annotation?What are the Steps of Image Annotation?What are the Different Techniques of Image Annotation?Types Used in Image AnnotationHow are Companies Handling Image Annotation?Features to Look for in Image Annotation Service Providers...
- 295 Views
- 2 replies
- 2 kudos

- 2 kudos
Great overview of image annotation! The sections on different techniques, real-world use cases, and pricing factors are especially helpful for anyone getting started with AI/ML. Looking forward to exploring the future trends in image annotation!
- 2 kudos
- 380 Views
- 2 replies
- 1 kudos
Tuning with Optuna and MlflowSparkStudy
I am following the guide for tuning a model with Optuna and MlflowSparkStudy. My compute is configured with autoscaling enabled, with 1–2 Spark workers, each with 8 cores and 32 GB of memory. I set n_jobs=2 and trials=100, in mlflow_study.optimize()....
- 380 Views
- 2 replies
- 1 kudos
- 1 kudos
Great questions—especially the distinction between Optuna’s trial-level parallelism and LightGBM’s intra-trial threading. The interaction with Spark autoscaling and data locality is also something I’d love to see documented with a concrete example. C...
- 1 kudos
- 475 Views
- 1 replies
- 4 kudos
End-to-End Streaming NLP Pipeline with GDELT, Azure Data Factory, ADLS Gen2 and Databricks
Building an End-to-End Streaming NLP Pipeline with GDELT, Azure Data Factory, ADLS Gen2 and DatabricksI recently worked on an end-to-end streaming NLP project using GDELT news data, Azure Data Factory, ADLS Gen2 and Azure Databricks.The goal was not ...
- 475 Views
- 1 replies
- 4 kudos
- 4 kudos
Great end-to-end project! To take it to the next level, consider exploring these native Databricks capabilities.Lakehouse Monitoring: Track data drift and automate model retraining when performance drops.Model Serving: Deploy your models behind serve...
- 4 kudos
- 745 Views
- 4 replies
- 3 kudos
End-to-End Streaming NLP Pipeline with GDELT, Azure Data Factory, ADLS Gen2 and Databricks
I have been working on a project to understand Databricks end to end, rather than just loading some data and training a model.I picked GDELT news data and the use case is to identify supply chain disruption related news and eventually predict which e...
- 745 Views
- 4 replies
- 3 kudos
- 3 kudos
@kartheek_rao, you are on the right track.Since you are doing clustering of new articles, it's unsupervised learning; you need to understand the feature engineering part more and the EDA part with MLFlow experiments. You have model monitoring as well...
- 3 kudos

- 581 Views
- 2 replies
- 1 kudos
Model Serving An internal error occurred during feature store lookup all deploys failing
We can't deploy models to Model Serving. Failures started around 2026-08-16 and were intermittent at first — our current production config deployed cleanly on 08-20 — but since then every attempt fails at the feature store lookup setup step, with no ...
- 581 Views
- 2 replies
- 1 kudos
- 1 kudos
Update — reproduced at minimum complexity, and the failure is unobservableWe stopped theorising and bisected with a deliberately trivial model: SimpleImputer + LogisticRegression, logged with fe.log_model, no custom code, on an online store created t...
- 1 kudos
- 939 Views
- 1 replies
- 1 kudos
Resolved! Traffic split behavior when traffic_percentage values across served entities sum to more than 100%
Hi all,I'm configuring a Model Serving endpoint with two served entities and ran into some unexpected behavior while testing different traffic_config splits.When I set traffic_percentage to 100 for each of the two served entities (so the total sums t...
- 939 Views
- 1 replies
- 1 kudos

- 1 kudos
Hi, Just been looking into this for you. All the docs I found suggested it would reject to I tried testing it myself. I tried setting traffic_config with various percentage combinations that don't sum to 100, on both Azure and AWS: Config (A / B) ...
- 1 kudos
- 1662 Views
- 1 replies
- 1 kudos
Resolved! Can Databricks Jobs Run on Kubernetes Clusters?
Context: We're exploring using Kubernetes (EKS) as our compute infrastructure instead of Databricks managed clusters. We want to understand if Databricks can orchestrate, deploy, and monitor jobs that run on a Kubernetes cluster.Questions:Is it possi...
- 1662 Views
- 1 replies
- 1 kudos

- 1 kudos
Hi @ASH1243434 ,Unfortunately, the Databricks cannot natively route job execution into your EKS cluster. There is no "external compute" or "bring your own Kubernetes" option in Databricks Jobs configuration. If my answer was helpful, please consider ...
- 1 kudos
- 1117 Views
- 2 replies
- 0 kudos
Memory error in LightGBM training data processing
I am developing a LightGBM model on Databricks, and I am using the Native API because it offers the widest range of options and allows me to try various approaches.The training data is loaded from a table in the Catalog as a Spark DataFrame. However,...
- 1117 Views
- 2 replies
- 0 kudos
- 2909 Views
- 2 replies
- 1 kudos
Resolved! Which types of model serving endpoints have health metrics available?
I am retrieving a list of model serving endpoints for my workspace via this API: https://docs.databricks.com/api/workspace/servingendpoints/listAnd then going to retrieve health metrics for each one with: https://[DATABRICKS_HOST]/api/2.0/serving-end...
- 2909 Views
- 2 replies
- 1 kudos

- 1 kudos
Your observation is correct—this behavior is expected.Endpoints with entity_type = FOUNDATION_MODEL_API do not expose health metrics via the /metrics endpoint, which is why you’re getting 404 responses. These endpoints are fully managed, multi-tenant...
- 1 kudos
- 2551 Views
- 7 replies
- 3 kudos
MLFlow Detailed Trace view doesn't work in some workspaces
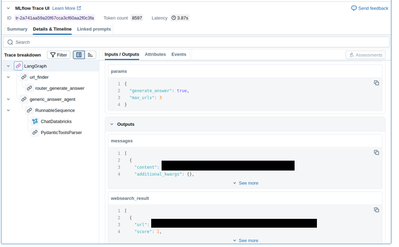
I've created a Databricks Model Serving Endpoint which serves an MLFlow Pyfunc model. The model uses langchain and I'm using mlflow.langchain.autolog().At my company we have some production(-like) workspaces where users cannot e.g. run Notebooks and ...


- 2551 Views
- 7 replies
- 3 kudos
- 3 kudos
Funnily enough, the problem also disappeard on my end this morning Previously, I saw a networking issue in my logs, but that also went away. Let's hope it stays that way!
- 3 kudos
- 2650 Views
- 1 replies
- 0 kudos
Databricks Model Serving Scaling Logic
Hi everyone,I’m seeking technical clarification on how Databricks Model Serving handles request queuing and autoscaling for CPU-intensive tasks. I am deploying a custom model for text and image extraction from PDFs (using Tesseract), and I’m struggli...
- 2650 Views
- 1 replies
- 0 kudos
- 0 kudos
TLDR: Pre-provision min_provisioned_concurrency ≥ your peak parallel requests (in multiples of 4) with scale-to-zero disabled, and chunk large PDFs in your model code to bound per-request latency — reactive autoscaling can't help CPU-bound workloads ...
- 0 kudos
- 2702 Views
- 4 replies
- 1 kudos
Params with databricks Asset bundles
Hello,I am using Databricks Asset bundels to create jobs for machine learning pipelines.My problem is I am using SparkPython taks and defining params inside those. When the job is created it is created with some params. When I want to run the same jo...
- 2702 Views
- 4 replies
- 1 kudos

- 1 kudos
Hi @Dali1, Great questions -- parameterizing ML pipelines in DABs is something a lot of people wrestle with, so let me break down the options. THE SHORT ANSWER No, you should not have to update the job definition every time you want different paramet...
- 1 kudos
- 1904 Views
- 1 replies
- 1 kudos
Resolved! Model Serving Only Shows WARNING/ERROR Logs
Hi everyone,I’m deploying a custom model using mlflow.pyfunc.PythonModel in Databricks Model Serving. Inside my wrapper code, I configured logging as follows:logging.basicConfig( stream=sys.stdout, level=logging.INFO, format='%(asctime)s ...
- 1904 Views
- 1 replies
- 1 kudos
- 1 kudos
@fede_bia This is worth walking through carefully. this is a common source of confusion when deploying custom models on Databricks Model Serving. SHORT ANSWER The default root logging level for Model Serving endpoints is set to WARNING. That is why y...
- 1 kudos
- 1721 Views
- 2 replies
- 2 kudos
Resolved! Python environment DAB
Hello,I am building a pipeline using DAB.The first step of the dab is to deploy my library as a wheel.The pipeline is run on a shared databricks cluster.When I run the job I see that the job is not using exactly the requirements I specified but it us...
- 1721 Views
- 2 replies
- 2 kudos

- 2 kudos
Hi @Dali1, +1 to @pradeep_singh, on shared clusters, tasks inherit cluster-installed libraries, so you won’t get a clean, versioned environment. Use a job cluster (new_cluster) or switch to serverless jobs with an environment per task for isolation. ...
- 2 kudos
- 1266 Views
- 1 replies
- 0 kudos
Resolved! Install library in notebook
Hello ,I tried installing a custom library in my databricks notebook that is in a git folder of my worskpace.The installation looks successfulI saw the library in the list of libraries but when I want to import it I have : ModuleNotFoundError: No mod...
- 1266 Views
- 1 replies
- 0 kudos
- 0 kudos
Just found the issue - The installation with editable mode doesnt work you have to install it as a library I don't know why
- 0 kudos
-
Access control
3 -
Access Data
2 -
AccessKeyVault
1 -
ADB
2 -
Airflow
1 -
Amazon
2 -
Apache
1 -
Apache spark
3 -
APILimit
1 -
Artifacts
1 -
Audit
1 -
Autoloader
6 -
Autologging
2 -
Automation
2 -
Automl
47 -
Aws databricks
1 -
AWSSagemaker
1 -
Azure
32 -
Azure active directory
1 -
Azure blob storage
2 -
Azure data lake
1 -
Azure Data Lake Storage
3 -
Azure data lake store
1 -
Azure databricks
32 -
Azure event hub
1 -
Azure key vault
1 -
Azure sql database
1 -
Azure Storage
2 -
Azure synapse
1 -
Azure Unity Catalog
1 -
Azure vm
1 -
AzureML
2 -
Bar
1 -
Beta
1 -
Better Way
1 -
BI Integrations
1 -
BI Tool
1 -
Billing and Cost Management
1 -
Blob
1 -
Blog
1 -
Blog Post
1 -
Broadcast variable
1 -
Business Intelligence
1 -
CatalogDDL
1 -
Centralized Model Registry
1 -
Certification
2 -
Certification Badge
1 -
Change
1 -
Change Logs
1 -
Check
2 -
Classification Model
1 -
Cloud Storage
1 -
Cluster
10 -
Cluster policy
1 -
Cluster Start
1 -
Cluster Termination
2 -
Clustering
1 -
ClusterMemory
1 -
CNN HOF
1 -
Column names
1 -
Community Edition
1 -
Community Edition Password
1 -
Community Members
1 -
Company Email
1 -
Condition
1 -
Config
1 -
Configure
3 -
Confluent Cloud
1 -
Container
2 -
ContainerServices
1 -
Control Plane
1 -
ControlPlane
1 -
Copy
1 -
Copy into
2 -
CosmosDB
1 -
Courses
2 -
Csv files
1 -
Dashboards
1 -
Data
8 -
Data Engineer Associate
1 -
Data Engineer Certification
1 -
Data Explorer
1 -
Data Ingestion
2 -
Data Ingestion & connectivity
11 -
Data Quality
1 -
Data Quality Checks
1 -
Data Science & Engineering
2 -
databricks
5 -
Databricks Academy
3 -
Databricks Account
1 -
Databricks AutoML
9 -
Databricks Cluster
3 -
Databricks Community
5 -
Databricks community edition
4 -
Databricks connect
1 -
Databricks dbfs
1 -
Databricks Feature Store
1 -
Databricks Job
1 -
Databricks Lakehouse
1 -
Databricks Mlflow
4 -
Databricks Model
2 -
Databricks notebook
10 -
Databricks ODBC
1 -
Databricks Platform
1 -
Databricks Pyspark
1 -
Databricks Python Notebook
1 -
Databricks Runtime
9 -
Databricks SQL
8 -
Databricks SQL Permission Problems
1 -
Databricks Terraform
1 -
Databricks Training
2 -
Databricks Unity Catalog
1 -
Databricks V2
1 -
Databricks version
1 -
Databricks Workflow
2 -
Databricks Workflows
1 -
Databricks workspace
2 -
Databricks-connect
1 -
DatabricksContainer
1 -
DatabricksML
6 -
Dataframe
3 -
DataSharing
1 -
Datatype
1 -
DataVersioning
1 -
Date Column
1 -
Dateadd
1 -
DB Notebook
1 -
DB Runtime
1 -
DBFS
5 -
DBFS Rest Api
1 -
Dbt
1 -
Dbu
1 -
DDL
1 -
DDP
1 -
Dear Community
1 -
DecisionTree
1 -
Deep learning
4 -
Default Location
1 -
Delete
1 -
Delt Lake
4 -
Delta lake table
1 -
Delta Live
1 -
Delta Live Tables
6 -
Delta log
1 -
Delta Sharing
3 -
Delta-lake
1 -
Deploy
1 -
DESC
1 -
Details
1 -
Dev
1 -
DevOps
1 -
Df
1 -
Different Notebook
1 -
Different Parameters
1 -
DimensionTables
1 -
Directory
3 -
Disable
1 -
Distribution
1 -
DLT
6 -
DLT Pipeline
3 -
Dolly
5 -
Dolly Demo
2 -
Download
2 -
EC2
1 -
Emr
2 -
Ensemble Models
1 -
Environment Variable
1 -
Epoch
1 -
Error handling
1 -
Error log
2 -
Eventhub
1 -
Example
1 -
Experiments
4 -
External Sources
1 -
Extract
1 -
Fact Tables
1 -
Failure
2 -
Feature Lookup
2 -
Feature Store
63 -
Feature Store API
2 -
Feature Store Table
1 -
Feature Table
6 -
Feature Tables
4 -
Features
2 -
FeatureStore
2 -
File Path
2 -
File Size
1 -
Fine Tune Spark Jobs
1 -
Forecasting
2 -
Forgot Password
2 -
Garbage Collection
1 -
Garbage Collection Optimization
1 -
Github
2 -
Github actions
2 -
Github Repo
2 -
Gitlab
1 -
GKE
1 -
Global Init Script
1 -
Global init scripts
4 -
Governance
1 -
Hi
1 -
Horovod
1 -
Html
1 -
Hyperopt
4 -
Hyperparameter Tuning
2 -
Iam
1 -
Image
3 -
Image Data
1 -
Inference Setup Error
1 -
INFORMATION
1 -
Input
1 -
Insert
1 -
Instance Profile
1 -
Int
2 -
Interactive cluster
1 -
Internal error
1 -
Invalid Type Code
1 -
IP
1 -
Ipython
1 -
Ipywidgets
1 -
JDBC Connections
1 -
Jira
1 -
Job
4 -
Job Parameters
1 -
Job Runs
1 -
Join
1 -
Jsonfile
1 -
Kafka consumer
1 -
Key Management
1 -
Kinesis
1 -
Lakehouse
1 -
Large Datasets
1 -
Latest Version
1 -
Learning
1 -
Limit
3 -
LLM
3 -
LLMs
4 -
Local computer
1 -
Local Machine
1 -
Log Model
2 -
Logging
1 -
Login
1 -
Logs
1 -
Long Time
2 -
Low Latency APIs
2 -
LTS ML
3 -
Machine
3 -
Machine Learning
24 -
Machine Learning Associate
1 -
Managed Table
1 -
Max Retries
1 -
Maximum Number
1 -
Medallion Architecture
1 -
Memory
3 -
Metadata
1 -
Metrics
3 -
Microsoft azure
1 -
ML Lifecycle
4 -
ML Model
4 -
ML Practioner
3 -
ML Runtime
1 -
MlFlow
75 -
MLflow API
5 -
MLflow Artifacts
2 -
MLflow Experiment
6 -
MLflow Experiments
3 -
Mlflow Model
10 -
Mlflow registry
3 -
Mlflow Run
1 -
Mlflow Server
5 -
MLFlow Tracking Server
3 -
MLModels
2 -
Model Deployment
4 -
Model Lifecycle
6 -
Model Loading
2 -
Model Monitoring
1 -
Model registry
5 -
Model Serving
35 -
Model Serving Cluster
2 -
Model Serving REST API
6 -
Model Training
2 -
Model Tuning
1 -
Models
8 -
Module
3 -
Modulenotfounderror
1 -
MongoDB
1 -
Mount Point
1 -
Mounts
1 -
Multi
1 -
Multiline
1 -
Multiple users
1 -
Nested
1 -
New Feature
1 -
New Features
1 -
New Workspace
1 -
Nlp
3 -
Note
1 -
Notebook
6 -
Notification
2 -
Object
3 -
Onboarding
1 -
Online Feature Store Table
1 -
OOM Error
1 -
Open Source MLflow
4 -
Optimization
2 -
Optimize Command
1 -
OSS
3 -
Overwatch
1 -
Overwrite
2 -
Packages
2 -
Pandas udf
4 -
Pandas_udf
1 -
Parallel
1 -
Parallel processing
1 -
Parallel Runs
1 -
Parallelism
1 -
Parameter
2 -
PARAMETER VALUE
2 -
Partner Academy
1 -
Pending State
2 -
Performance Tuning
1 -
Photon Engine
1 -
Pickle
1 -
Pickle Files
2 -
Pip
2 -
Points
1 -
Possible
1 -
Postgres
1 -
Pricing
2 -
Primary Key
1 -
Primary Key Constraint
1 -
Progress bar
2 -
Proven Practices
2 -
Public
2 -
Pymc3 Models
2 -
PyPI
1 -
Pyspark
6 -
Python
21 -
Python API
1 -
Python Code
1 -
Python Function
3 -
Python Libraries
1 -
Python Packages
1 -
Python Project
1 -
Pytorch
3 -
Reading-excel
2 -
Redis
2 -
Region
1 -
Remote RPC Client
1 -
RESTAPI
1 -
Result
1 -
Runtime update
1 -
Sagemaker
1 -
Salesforce
1 -
SAP
1 -
Scalability
1 -
Scalable Machine
2 -
Schema evolution
1 -
Script
1 -
Search
1 -
Security
2 -
Security Exception
1 -
Self Service Notebooks
1 -
Server
1 -
Serverless
1 -
Serving
1 -
Shap
2 -
Size
1 -
Sklearn
1 -
Slow
1 -
Small Scale Experimentation
1 -
Source Table
1 -
Spark config
1 -
Spark connector
1 -
Spark Error
1 -
Spark MLlib
2 -
Spark Pandas Api
1 -
Spark ui
1 -
Spark Version
2 -
Spark-submit
1 -
SparkML Models
2 -
Sparknlp
3 -
Spot
1 -
SQL
19 -
SQL Editor
1 -
SQL Queries
1 -
SQL Visualizations
1 -
Stage failure
2 -
Storage
3 -
Stream
2 -
Stream Data
1 -
Structtype
1 -
Structured streaming
2 -
Study Material
1 -
Summit23
2 -
Support
1 -
Support Team
1 -
Synapse
1 -
Synapse ML
1 -
Table
4 -
Table access control
1 -
Tableau
1 -
Task
1 -
Temporary View
1 -
Tensor flow
1 -
Test
1 -
Timeseries
1 -
Timestamps
1 -
TODAY
1 -
Training
6 -
Transaction Log
1 -
Trying
1 -
Tuning
2 -
UAT
1 -
Ui
1 -
Unexpected Error
1 -
Unity Catalog
12 -
Use Case
2 -
Use cases
1 -
Uuid
1 -
Validate ML Model
2 -
Values
1 -
Variable
1 -
Vector
1 -
Versioncontrol
1 -
Visualization
2 -
Web App Azure Databricks
1 -
Weekly Release Notes
2 -
Whl
1 -
Worker Nodes
1 -
Workflow
2 -
Workflow Jobs
1 -
Workspace
2 -
Write
1 -
Writing
1 -
Z-ordering
1 -
Zorder
1
- « Previous
- Next »